Anthropic Launches Message Threads to Reduce Latency in Claude AI Agent Sessions by 35%


3 Sources
[1]
Is Claude Code truly faster with message threads? I did the math on my logs
Claude Code's update could save you time during demanding, hours-long coding sessions at no extra cost. But by how much? Here's my real-world result. * Anthropic's message threads make Claude Code a tad more responsive. * My tests suggest savings of 2 to 4 minutes per coding session. * You get
[2]
Anthropic's message threads let Claude agents skip resending chats
The beta cuts the wait before Claude replies in long sessions by about a third, Anthropic says. Anthropic launched message threads in public beta for its API. Agents send the full conversation once, then only new messages, which Anthropic says cuts the wait before Claude replies by about 35% on
[3]
Anthropic Introduces Message Threads
It is designed to improve the efficiency of long-running conversation Anthropic has introduced Message Threads in public beta on the Claude Platform. The new feature is intended to reduce response latency in long-running AI agent sessions. It eliminates the need to resend the entire conversation
Share
Copy Link
Anthropic introduced message threads in public beta for Claude, cutting response latency by 35% for long-running AI agent sessions. The feature eliminates resending conversation history with each API request, making Claude Code and other agents more responsive without changing token costs or rate limits.
Anthropic Introduces Message Threads to Optimize Claude Performance
Anthropic has launched message threads in public beta for its Claude platform, fundamentally changing how AI agent interactions handle conversation history
1
2
. The feature addresses a longstanding inefficiency where agents had to resend entire conversation histories with every API request, creating significant delays in long-running AI agent sessions3
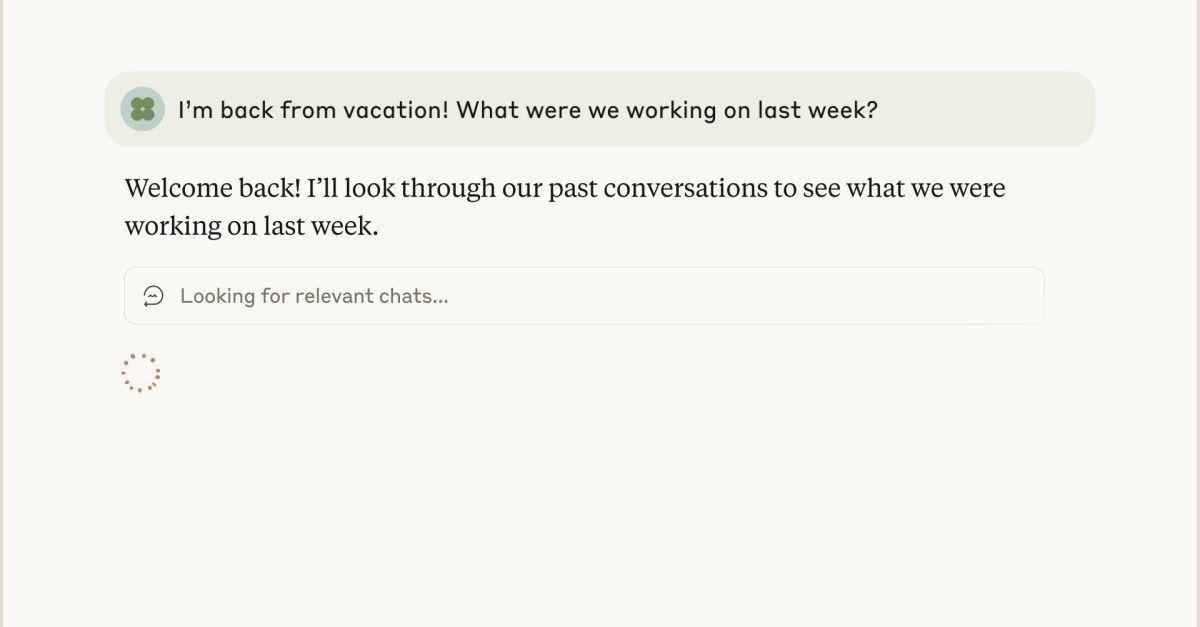
. With message threads, developers now send the full conversation once, then submit only new messages along with the ID of the previous response for subsequent requests2
.
Source: The Next Web
The innovation targets a critical bottleneck in agent workflows. Before message threads, every request required resending conversation history—similar to texting a friend while attaching every previous message in the thread each time
1
. Coding agents making hundreds of requests in one session faced mounting delays as context grew to hundreds of thousands of tokens2
. This repetitive data transmission slowed response times, particularly impacting sessions approaching Claude's maximum context window.Performance Gains and Real-World Impact
Anthropic reports message threads reduce latency by approximately 35% for requests containing 500,000 to 1 million tokens
3
. The benefit manifests as faster time to first token—the delay before Claude begins responding. Real-world testing suggests tangible improvements during extended coding sessions. Analysis of roughly 980 turns in Claude Code logs showed responses typically began about 3 seconds after each request in contexts exceeding 500,000 tokens1
. During busy sessions making 100 to 225 model calls over four hours, the projected savings reach 2 to 4 minutes per session1
.
Source: ZDNet
While minutes may seem modest, the impact scales significantly. About half of intensive sessions hit the context ceiling multiple times nightly
1
. For computer-using agents that transmit screenshots repeatedly, those images now stay with the thread instead of being re-uploaded every turn1
. In enterprise deployments or applications requiring rapid AI responses, any reduction in latency becomes critical, especially for workflows involving substantial back-and-forth exchanges with large data payloads1
.Technical Implementation and Availability
Message threads are enabled by default for most Claude Code users
3
. API users activate the feature by adding the thread parameter to Messages API requests1
. The first request includes the full conversation and initiates a thread. Subsequent requests carry only new messages plus the previous response ID3
. Conversation threads are temporarily maintained in memory between requests, encrypted and never written to disk2
. Threads expire five minutes after the last request, requiring developers to maintain their own conversation copies2
.The public beta works across all Claude models on Anthropic's native platform, AWS, Microsoft Foundry, and Google Cloud with Anthropic-managed models
3
. Anthropic confirmed threads are not eligible for zero data retention or HIPAA health-data configurations2
.Related Stories
Cost Implications and Context Management
Message threads deliver faster responses without changing token costs. Claude still processes the full conversation during every turn, keeping token usage and pricing identical
1
2
. Rate limits also remain unchanged3
. The feature provides performance gains at no extra cost, though it doesn't reduce expenses1
. For cost savings, developers can combine message threads with prompt caching, which has been available for about two years and prevents re-processing prompts repeatedly1
.Message threads don't eliminate context management challenges or improve Claude's reasoning capabilities
1
. Context size—roughly equivalent to working memory—still maxes out at around 1 million tokens for most Claude Code sessions1
. Compaction processes that reduce information to fit available context remain necessary. Individual one-off requests see no improvement, and conversations delayed longer than 5 minutes between turns revert to sending full message contents1
. The feature proves particularly valuable for long-running coding agents, computer-use agents, and document- and image-heavy workflows3
.References
Summarized by

Navi
[3]
Related Stories
Anthropic Unifies Claude AI With New Docs and Slides Tools in Single Interface Overhaul
17 Sept 2026•Technology
Anthropic Launches Claude Code Projects With AI Orchestration for Cloud Developers
18 Sept 2026•Technology
Anthropic Boosts Claude AI with Massive Context Window and Improved Opus Model
06 Aug 2025•Technology
Recent Highlights


Recent Highlights
Today's Top Stories




Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


