doubleAI's Maxwell code execution model slashes compute costs by 67% as Nvidia and Dell invest $220M


5 Sources
[1]
doubleAI's Maxwell rewrites code as it runs to cut compute costs
Maxwell rewrites the machine code under running programs and proves each change correct, the company says. One early customer cut its compute costs by 67%, doubleAI told The Wall Street Journal. Amnon Shashua's startup doubleAI has launched Maxwell, an AI model that works inside running software
[2]
Nvidia-backed doubleAI launches AI model that cuts compute costs
The startup, co-founded by Mobileye CEO Amnon Shashua, plans to charge customers a share of the compute savings it delivers DoubleAI, a Tel Aviv-based startup backed by Nvidia $NVDA, has launched an AI model that it says lowered the compute spending of one early customer by 67%, according to The
[3]
AI startup doubleAI debuts Maxwell 'code execution model'
Startup doubleAI today debuted Maxwell, a model that can optimize software code and generate mathematical proofs. Tel Aviv-based doubleAI, officially AA-I Technologies Ltd., is led by Chief Executive Officer Amnon Shashua, who earlier co-founded auto chip supplier Mobileye Global Inc. The company
[4]
Nvidia, Dell back $200M round for AI model developer doubleAI
Artificial intelligence developer doubleAI today announced that it has raised $200 million in funding. Lightspeed and Bessemer co-led the Series A round. They were joined by Nvidia Corp., Dell Technologies Inc. and several others. CTech reported that the investment values doubleAI at more than $1
[5]
Nvidia-Backed Double AI Debuts AI 'Code Execution' Models | PYMNTS.com
Israeli startup DoubleAI is reportedly set to introduce what it describes as a new category of artificial intelligence (AI). The company, whose backers include Nvidia and Dell, calls this new category "code execution" models (CEMs) which place the AI "between code and silicon," the Wall Street
Share
Copy Link
Tel Aviv startup doubleAI, led by Mobileye co-founder Amnon Shashua, has launched Maxwell—the first code execution model that rewrites machine code during runtime to optimize software efficiency. The AI model that cuts compute costs helped one early customer reduce spending by 67% while doubling inference speed for LTX's multimodal models.
doubleAI launches Maxwell to autonomously improve code performance
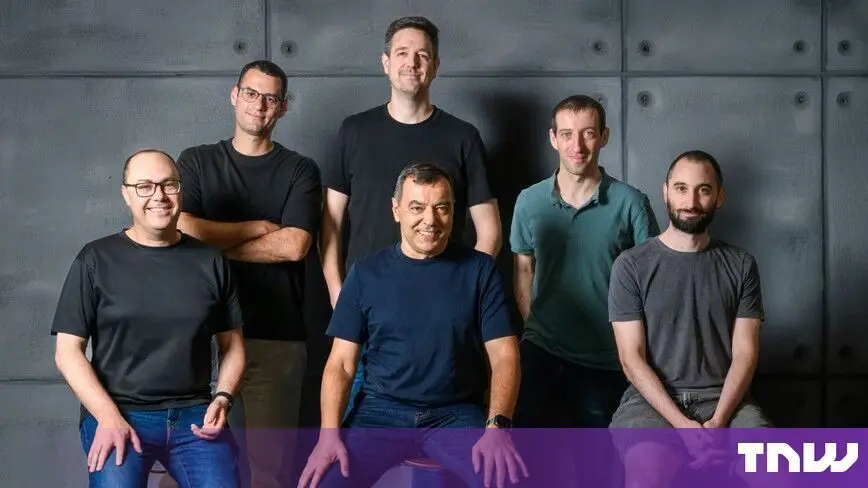
Tel Aviv-based startup doubleAI has introduced Maxwell, an AI model that cuts compute costs by optimizing software while it runs. Co-founded by Amnon Shashua, who also leads autonomous driving company Mobileye, doubleAI announced Maxwell on Monday and opened early access to what it calls the first code execution model (CEM).
1
Unlike large language models that help write source code, Maxwell operates inside running programs and rewrites code as it runs to optimize software efficiency without human intervention.2
Source: The Next Web
The company raised $220 million in total funding, with a $200 million Series A co-led by Lightspeed and Bessemer Venture Partners.
3
Nvidia, Dell Technologies Capital, Greenfield, Pitango and BRM also participated in the round, valuing the two-year-old company at more than $1 billion.4
The startup allocated roughly half its funding to purchase 1,000 Nvidia B300 chips for its own computing needs, with Shashua noting that "you cannot rely just on renting compute. Prices are going up."1
How Maxwell rewrites code as it runs to reduce AI workload hardware usage
Maxwell works by watching programs during runtime and optimizes programs at the binary level—the machine code that processors actually execute—rather than modifying source code.
3
The AI-driven software optimization analyzes how programs interact with data and underlying hardware, supporting both GPU and CPU environments. When Maxwell identifies optimization opportunities, it formally and mathematically proves each change maintains program behavior unchanged before implementation.2
Source: PYMNTS
"The main obstacle was verifying the code," Shashua explained. "DoubleAI found a way to perform that verification formally and mathematically."
2
If conditions supporting a faster code version stop holding, built-in guards automatically return control to the original code, ensuring reliability.1
The code execution model delivered dramatic performance improvements across real-world workloads. Maxwell made data pipelines more than 38 times faster and accelerated AI inference kernels by over 4.5 times.
1
One early customer reduced compute costs by 67%, while LTX, which builds open-weight multimodal models, doubled its model inference speed. "Halving the GPU time immediately translates to your serving costs, your margins," said Zeev Farbman, LTX co-founder and CEO.1
Maxwell tackles surging GPU and CPU prices with runtime optimization
The launch addresses escalating infrastructure expenses as demand for AI computing power outpaces supply. The hourly price to rent Nvidia H100 chip capacity under one-year contracts has jumped 60% over the past year, according to SemiAnalysis.
2
"More hardware is being built, but the need for compute is rising faster than the ability to build GPUs and CPUs," Shashua told The Wall Street Journal. "If you can utilize the hardware better, then you can achieve something incredible in terms of savings."2
doubleAI plans to charge customers based on savings generated, collecting a share of reduced spending rather than fixed fees. If Maxwell brings a customer's compute costs down from $10 million to $6 million, doubleAI would take a percentage of the $4 million saved, though the exact share remains undisclosed.
2
Shashua expects AI labs with massive training and inference bills, such as OpenAI and Anthropic, to benefit most. For these organizations, even a 10% reduction could translate to hundreds of millions in annual savings.1
Related Stories

Proven performance gains across cuGraph, pandas, and LTX-2.5
Maxwell has demonstrated its capabilities across multiple high-profile projects. In March, the code execution model rewrote Nvidia's open-source cuGraph library, which enables GPU-accelerated graph analytics for supply chain management and similar applications. Maxwell sped up 55% of cuGraph's algorithms by a factor of two or more.
3
The model subsequently optimized pandas, a widely-used data science toolkit, improving its performance on the PDS-H query speed benchmark by a factor of 38.4
Most recently, Maxwell doubled the video generation speed of LTX-2.5, a world model developed by LTX.
3
Beyond software optimization, Maxwell broke a nearly 50-year chess record by discovering a position where 63 moves give check, surpassing the previous 60-move record. A separate doubleAI agent made new mathematical discoveries about graphs, providing proofs with Lean verification files.4
What Maxwell means for enterprise AI spending and infrastructure
The code execution model arrives as finance teams increasingly seek AI agents to manage their organizations' AI expenditures. Research shows 43% of CFOs expect agents that continuously monitor spending patterns and reallocate budgets in real-time to have major impact.
5
Maxwell addresses this need by actively reducing costs during runtime rather than providing post-facto visibility."AI has changed how software is written, but not how it runs," Shashua stated.
1
By placing AI "between code and silicon," doubleAI's approach represents a shift from helping developers write better code to making existing code execute more efficiently on available hardware.5
With approximately 40 employees and broader release planned before month's end, doubleAI positions Maxwell to compete with OpenAI and Anthropic's latest models that also automate research tasks.
3
The company's investment in 1,000 B300 Blackwell GPUs signals its commitment to maintaining competitive infrastructure as the race to optimize AI workloads intensifies. As compute prices continue climbing and enterprises scrutinize AI spending, Maxwell's ability to deliver measurable savings through runtime optimization could reshape how organizations approach infrastructure costs.References
Summarized by

Navi
[1]
[3]
[4]
Related Stories
MatX AI chip startup raises $500 million to challenge Nvidia's dominance in LLM processing
25 Feb 2026•Startups
NVIDIA Blackwell Ultra slashes AI inference costs by 35x while delivering 50x better performance
12 Feb 2026•Technology
Elon Musk's xAI Secures $20 Billion in Innovative Financing Deal with Nvidia
08 Oct 2025•Technology

Recent Highlights


Recent Highlights
Today's Top Stories






Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


