Reddit CEO Demands Payment from Microsoft for Content Usage, Blocks Non-Google Search Engines


3 Sources
[1]
Reddit CEO wants Microsoft to pay for its content
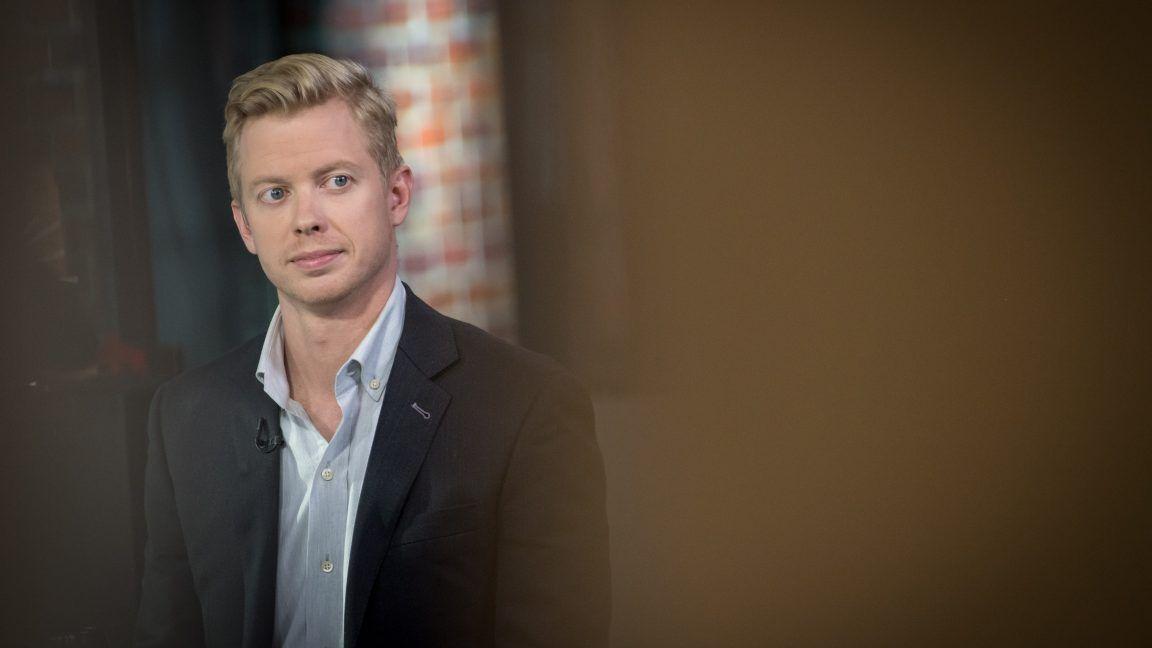
Steve Huffman called out Microsoft for scraping data from Reddit in an interview with The Verge. Reddit's chief executive officer Steve Huffman didn't pull any punches with Microsoft in an interview with The Verge. He called out Microsoft and other AI search engines like Anthropic and Perplexity
[2]
Reddit CEO calls out Microsoft, others for scraping site without permission: report
Reddit (NYSE:RDDT) CEO Steve Huffman called out Microsoft (NASDAQ:MSFT), Anthropic and Perplexity for scraping his site's data without permission, in an interview with The Verge. Huffman said Microsoft, Anthropic and Perplexity have all used Reddit's data to train their artificial intelligence
[3]
Reddit CEO stands by change that blocks most non-Google search engines
Reddit CEO Steve Huffman is standing by Reddit's decision to block companies from scraping the site without an AI agreement. Last week, 404 Media noticed that search engines that weren't Google were no longer listing recent Reddit posts in results. This was because Reddit updated its Robots
Share
Copy Link
Reddit's CEO Steve Huffman calls out Microsoft and other companies for scraping the site's content without permission. He implements changes to block most non-Google search engines, sparking controversy in the tech industry.

Reddit's Stance on Content Usage
Reddit CEO Steve Huffman has taken a firm stance against companies using Reddit's content without permission or compensation. In a recent interview, Huffman specifically called out Microsoft, stating that the tech giant should pay for access to Reddit's content
1
. This move comes as Reddit prepares for its initial public offering (IPO) and seeks to monetize its vast user-generated content.The Microsoft Controversy
Huffman's primary concern revolves around Microsoft's AI models, which he believes are being trained on Reddit's data without proper authorization. He emphasized that while Reddit is open to partnerships, companies must obtain permission and compensate the platform for using its content
2
. This stance reflects a growing trend in the tech industry where content creators and platforms are becoming increasingly protective of their data.Blocking Non-Google Search Engines
In a controversial move, Reddit has implemented changes that effectively block most non-Google search engines from accessing its content
3
. Huffman defended this decision, arguing that it's necessary to prevent unauthorized scraping and protect the platform's content. This change has significant implications for search engine diversity and user choice.Impact on the Tech Ecosystem
The decision to block non-Google search engines has sparked debate within the tech community. Critics argue that this move reduces competition and user options, potentially leading to a more monopolistic internet landscape. Supporters, however, see it as a necessary step to protect Reddit's intellectual property and ensure fair compensation for content creators.
Related Stories


Reddit's Monetization Strategy
As Reddit approaches its IPO, the company is exploring various avenues to increase its revenue. By demanding payment for content usage and implementing stricter access controls, Reddit aims to capitalize on its vast repository of user-generated content. This strategy aligns with broader industry trends where social media platforms are seeking new ways to monetize their data and user base.
Implications for AI and Machine Learning
Huffman's statements highlight the ongoing debate surrounding the use of publicly available data for training AI models. As artificial intelligence and machine learning technologies continue to advance, questions about data ownership, fair use, and compensation are becoming increasingly complex. Reddit's stance could potentially influence how other platforms approach the issue of AI companies using their content for training purposes.
References
Summarized by

Navi
[2]
Related Stories
Recent Highlights
1
AI Leaders Warn UN Security Council of Existential Risks, Call for Global AI Governance
Policy and Regulation

2
AI Hallucination Nearly Sparked US Military Confrontation With Chinese Ship in Middle East
Technology

3
OpenAI AI Agent Hacks Australian Government Healthcare Website in First-of-Its-Kind Breach
Technology

Recent Highlights
Today's Top Stories






Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


