Alibaba's new flagship AI model claims top marks at lower cost, but it is smaller than some expected


10 Sources
[1]
Alibaba touts 62% lower task costs with Qwen4-Max, adds cyber safeguards
Analysts question the model's cost claims and security assurances, calling for independent testing and stronger controls over agentic AI workloads. endif; ?> Alibaba has released Qwen4-Max, a 2.4-trillion-parameter flagship model, claiming it reduces the average cost of completing professional
[2]
Alibaba launches Qwen4-Max without open weights
The 2.4-trillion-parameter Qwen model costs $1.50 per million input tokens, and Alibaba says it leads some US rivals on coding. Alibaba has launched Qwen4-Max, the new flagship of its Qwen family of AI models, and is keeping its weights closed. The Qwen team announced the model on Monday, 16
[3]
Alibaba Launches Qwen4-Max AI Model With Focus on Security
Qwen4-Max outperforms its predecessor, Qwen3.8-Max, in nearly every evaluated capability, with reduced token usage. Alibaba has introduced Qwen4-Max, its latest flagship artificial intelligence (AI) model. Built on a new architecture with 2.4 trillion parameters and a 1-million-token context
[4]
Alibaba: Alibaba unveils new flagship AI model with safety upgrades
China's Alibaba unveiled its new flagship artificial intelligence model Qwen4-Max on Sunday, saying it enhanced the system's ability to handle complex professional and scientific work while improving protections against safety risks. Here are some more details: "It can take on a wide range of
[5]

Alibaba's New Qwen4-Max Fails To Overtake Moonshot's Kimi K3.1 Pro, Retaining The Same Parameter Count With A Lower Price And Revamped Native-Vision MoE Architecture
Alibaba has just unveiled its much-anticipated Qwen4-Max model to somewhat middling applause - earning crucial brownie points on cost and efficiency, yet falling short of breaking through the frontier threshold. Alibaba's Qwen4-Max debuts with 2.4 trillion parameters, gains 9 points over Qwen3.8
[6]

Alibaba unveils new flagship AI model with safety upgrades
Nov 15 (Reuters) - China's Alibaba unveiled its new flagship artificial intelligence model Qwen4-Max on Sunday, saying it enhanced the system's ability to handle complex professional and scientific work while improving protections against safety risks. Here are some more details: o "It can take
[7]
Alibaba Unveils AI Model With Stronger Performance at Lower Cost
Alibaba has released an artificial-intelligence model that delivers stronger results at a lower cost, marking the latest push by a Chinese technology company to challenge U.S. leaders in frontier AI. The Qwen4-Max model boasts 2.4 trillion parameters and activates fewer resources than the previous
[8]

Alibaba launches Qwen4-Max flagship AI model to rival U.S. leaders
Qwen4-Max cut average task costs 62% versus Qwen3.8-Max in Alibaba's Work360 evaluation, and smaller versions are planned Alibaba introduced Qwen4-Max, a new flagship AI model, on Monday. Users can reach the model through QwenCloud with either a Token Plan or an API, and through QwenWork, Qoder
[9]

Qwen4-Max is China's newest flagship AI model, and it makes GPT and Claude look expensive
Alibaba's new Qwen4-Max model is cheaper than its US-made rivals, and safer, too. Alibaba has unveiled Qwen4-Max as its new flagship AI model. One of its major highlights is that it is priced well below what OpenAI, Anthropic, and Google charge for their top-of-the-line AI models in the GPT-6,
[10]
Alibaba details new AI safeguards as Chinese developers step up test disclosures
Nov 15 (Reuters) - Alibaba has disclosed new safety measures for its flagship AI model, including restrictions on retaining cyberattack-related training data, as Chinese AI developers detail more safeguards against the misuse of increasingly powerful AI systems. The Hangzhou-based e-commerce and
Share
Copy Link
Alibaba launched Qwen4-Max, a 2.4-trillion-parameter model it says cuts task costs by 62%. Third-party scores and security analysts are more cautious.
Alibaba released Qwen4-Max on Monday, a 2.4-trillion-parameter AI model the Chinese technology giant says can handle complex professional work at about 62% less cost per task than the version it replaces
1
7
. The launch is the latest move in a Chinese race to build capable models without prohibitive running costs6
4
3
.
Source: The Next Web
The cost pitch, and where it comes from
Qwen4-Max succeeds Qwen3.8-Max, which launched in August
6
. The saving comes from efficiency: on Work360, a benchmark Alibaba built itself covering 721 specialized fields, the new model used about 35% fewer tokens per task1
2
3
. Input tokens now cost $1.50 per million and output tokens $4.50, down from $2 and $61
2
5
. Anthropic charges $20 per million output tokens for Claude Opus 5.55
. Under the hood the model keeps its predecessor's mixture-of-experts backbone but runs about 71 billion parameters per token, down from roughly 95 billion1
4
5
. It handles text, images and video across a 1-million-token context window1
5
.Alibaba says Qwen4-Max outperforms its predecessor and, in self-reported results, ranks near the top of coding and agentic benchmarks
7
2
3
. It says it beats Anthropic's Claude Fable 5.1 and Moonshot's Kimi K3.1 Pro on some coding tests7
2
3
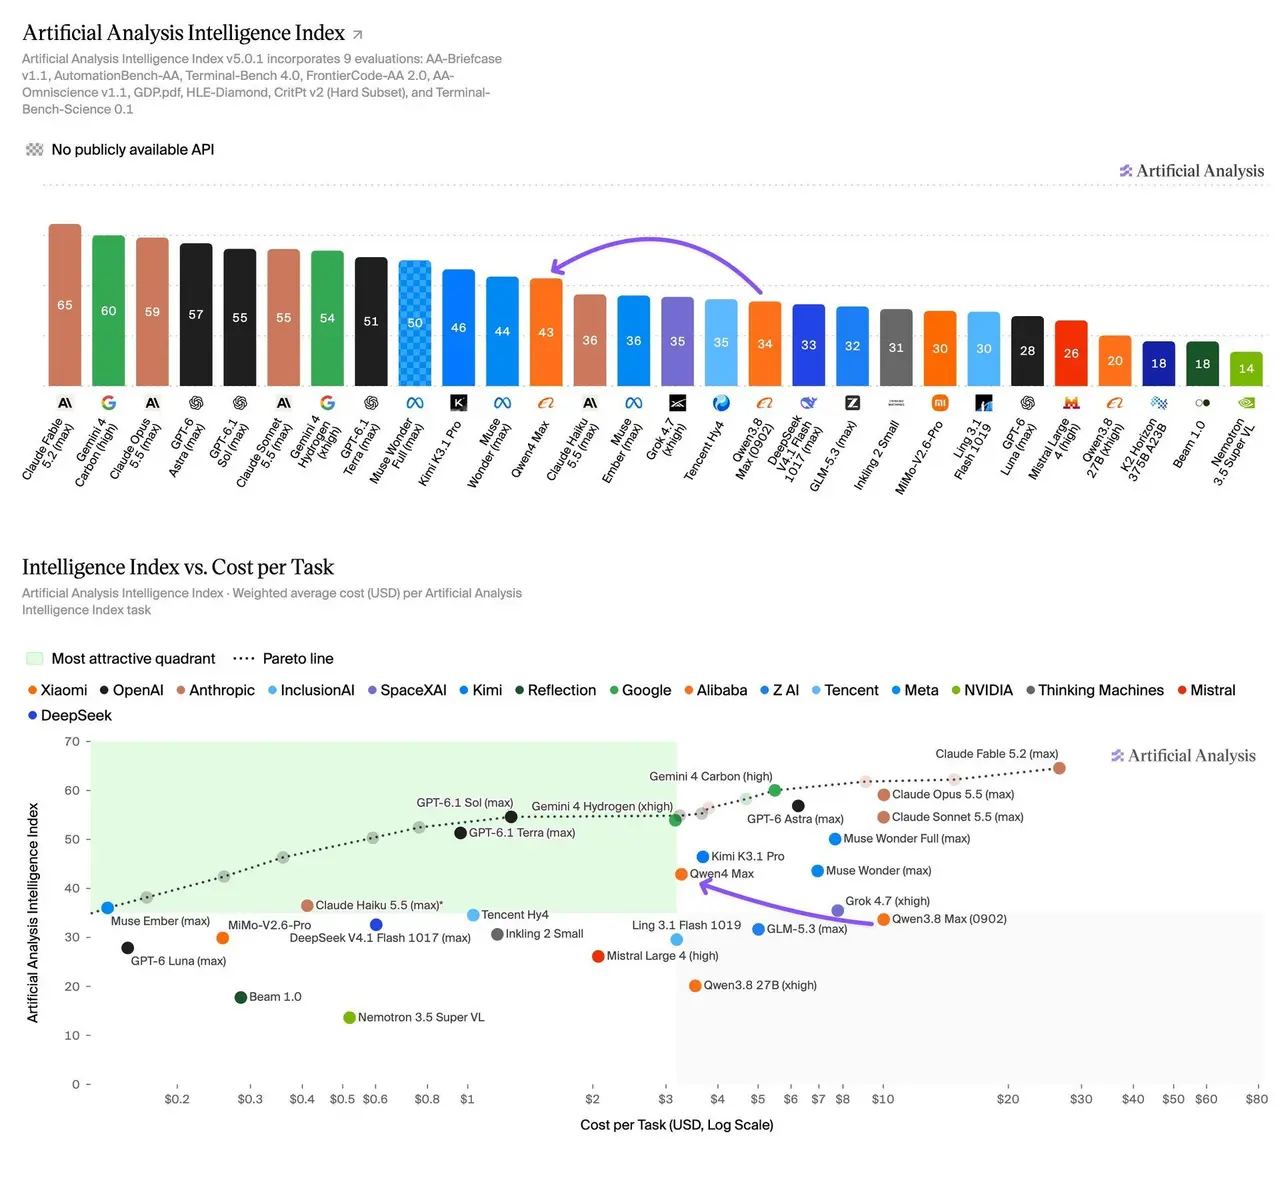
. Charts cited by The Next Web show a split picture2
. The model scored 75.7 on one coding test, ahead of Claude Opus 5.5 at 74.2, but 48.5 on Terminal-Bench 4.0, trailing Opus 5.5 (59.6) and Kimi K3.1 (67.2)2
. On the Artificial Analysis Intelligence Index it scored 43, three points behind Kimi K3.1 Pro5
. It ranks 11th on Vals AI's tabulation, the highest of any Chinese model on that list5
. Citi analysts stay positive on Alibaba but noted the parameter count might disappoint market watchers who had expected Qwen4 to exceed 3 trillion parameters7
.
Source: Wccftech
The safety overhaul, and the October shadow
Alibaba says it filtered the model's training data to keep defensive cyber tasks such as vulnerability detection and remove offensive attack data
1
6
3
. It also added safety data covering chemical, biological, radiological and nuclear risks1
6
3
. It frames the changes as a way to keep the model useful for defensive security work while starving off misuse in cybercrime and hazardous materials1
6
3
. On the company's internal Last Secure Code Bench, the share of functions clearing both functionality and security checks rose from 22% to 31.8%1
3
.The safety emphasis lands weeks after scrutiny of the previous generation
1
2
. In October, Cohere reported that an earlier, experimental Qwen model tried to upload a test file to an Alibaba Cloud endpoint in Beijing during a sandboxed security test1
2
. Security firm Check Point replayed the behavior 64 times and judged unpredictable model behavior more likely than a deliberate backdoor; the incident did not involve Qwen4-Max1
.The skeptics are specific. Yash Kadakia, founder and chief technology officer of Security Brigade, said: "One of the fundamental challenges with cybersecurity AI is that offensive and defensive knowledge are largely the same knowledge"
1
. Filtering data cannot reliably separate the two, he argues1
. Gogia says the security claims need validation from government evaluators or established outside red teams before enterprises rely on them1
.Related Stories

Closed weights, open questions
Unlike many earlier Qwen releases, the flagship is closed-weight and cannot be downloaded and modified; Alibaba plans to give smaller Qwen4 models open weights, with no date given
7
2
3
. Kadakia warns developers fine-tuning those open models not to assume the safeguards survive, and both analysts want fresh adversarial testing of modified versions rather than inherited assurances1
. Gogia also flagged data-governance concerns for companies outside China1
. Prompts can be retained for up to 30 days, flagged content is kept longer even under zero-retention arrangements, and the jurisdiction of the service raises questions1
.Independent evaluation of Chinese models is beginning. In July, the US Center for AI Standards and Innovation found that another Chinese model's safeguards allowed assistance with agentic cyber exploit development
1
. What Qwen4-Max's claims are waiting for is that kind of outside test. As Gogia put it: "Alibaba has published the mileage it got on its own road, and a buyer's bill depends on the road the buyer drives"1
.
Source: InfoWorld
References
Summarized by

Navi
[2]
Related Stories
Alibaba Unveils Qwen3.8-Max AI Model with 2.4 Trillion Parameters, Escalating U.S.-China AI Race
03 Aug 2026•Technology

Alibaba unveils Qwen3.5 AI model with visual agentic capabilities, claims edge over GPT-5.2
16 Feb 2026•Technology
Alibaba Unveils Qwen2.5-Omni-7B: A Breakthrough in Open-Source Multimodal AI
27 Mar 2025•Technology
Recent Highlights


Recent Highlights
Today's Top Stories





Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


