Nvidia accused of seeking pirated books from shadow library to train AI models amid lawsuit


4 Sources
[1]
Nvidia accused of trying to cut a deal with Anna's Archive for high‑speed access to the massive pirated book haul -- allegedly chased stolen data to fuel its LLMs
Court documents appear to show Nvidia management green lit the deal, despite Anna's Archive's warnings. Nvidia has been accused of offering to pay for 'high-speed access' to Anna's Archive, a notorious 'shadow library' portal, bursting with copyright-infringing materials. Documents published by
[2]
Nvidia allegedly greenlit the use of pirated books from illegal sources to train its AI models, according to an expanded class-action lawsuit
The capabilities of AI models, such as GPT-5, Gemini, Claude, and Grok, lie in the size and scope of the dataset used to train them. This has also been the source of multiple lawsuits, claiming that the companies performing the training had no right to freely use the data. In an expanded
[3]
Claim: NVIDIA green-lit pirated book downloads for AI training
NVIDIA executives authorized using millions of pirated books from Anna's Archive for AI training, according to an expanded class-action lawsuit. The suit, citing internal NVIDIA documents, alleges the company contacted Anna's Archive for high-speed access to its data. NVIDIA has benefited from the
[4]
Lawsuit alleges NVIDIA approved use of pirated books to train AI models
TL;DR: A lawsuit alleges NVIDIA executives approved partnering with Anna's Archive, a site hosting millions of pirated books and papers, to use its data for training Large Language Models. Internal emails reveal NVIDIA sought access to 500 terabytes of illegally obtained content amid competitive
Share
Copy Link
Nvidia faces expanded allegations in a class-action lawsuit claiming the company sought high-speed access to 500 terabytes of pirated books from Anna's Archive for AI training. Internal emails reportedly show management approved the deal despite warnings about illegally obtained data, raising questions about how tech giants source training data for their language models.
Nvidia contacted shadow library for AI training data, lawsuit alleges
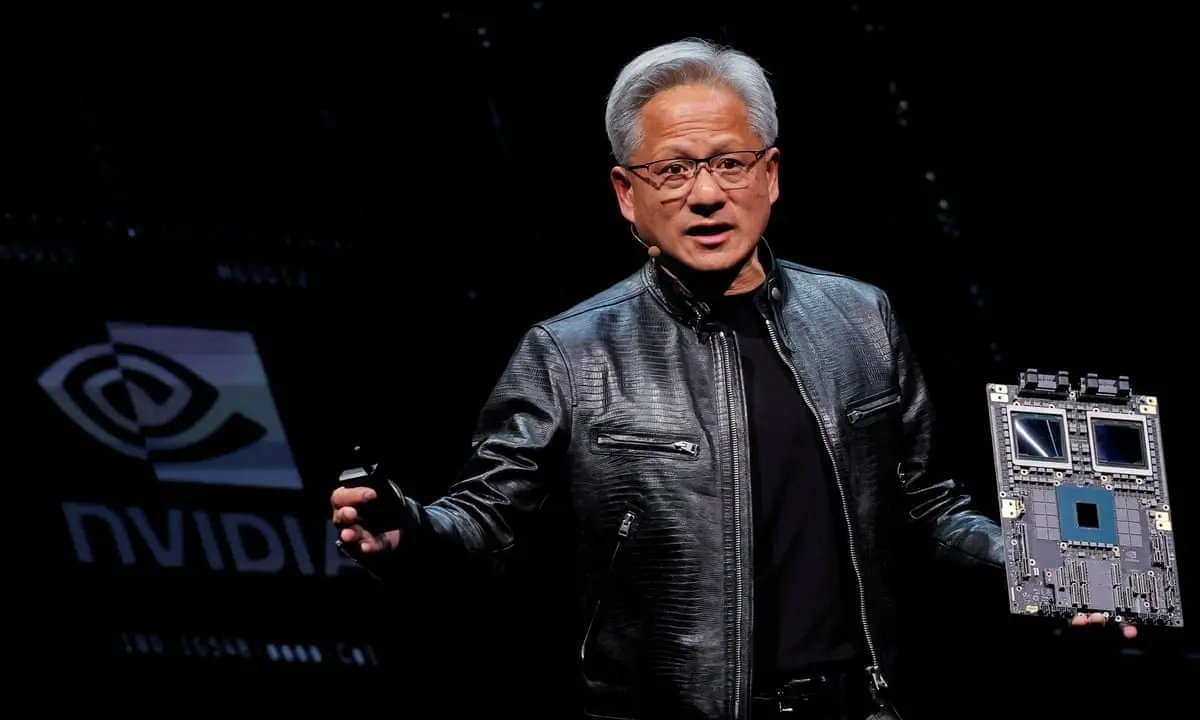
Nvidia has been accused of attempting to secure high-speed access to Anna's Archive, a notorious shadow library containing millions of pirated books, to fuel its AI training efforts. According to an amended complaint filed in the U.S. District Court for the Northern District of California, internal emails reveal that the Nvidia data strategy team contacted Anna's Archive to explore using its massive repository for pre-training Large Language Models
1
2
. The lawsuit, which now includes authors Abdi Nazemian, Brian Keene, Stewart O'Nan, Andre Dubus III, and Susan Orlean, significantly expands the scope of copyright infringement claims against the GPU giant3
.
Source: TweakTown
Court documents show management approval despite warnings
The amended complaint cites internal Nvidia communications that appear damning. One email snippet shows an unnamed Nvidia executive writing: "we are exploring including Anna's Archive in pre-training data for our LLMs" and seeking "to get a better understanding of LLM-related work you have done"
2
. More significantly, the complaint alleges that Anna's Archive warned Nvidia that its library content was illegally obtained and maintained, yet "within a week of contacting Anna's Archive, and days after being warned by Anna's Archive of the illegal nature of their collections, Nvidia management gave 'the green light' to proceed with the piracy"1
. Anna's Archive reportedly charged tens of thousands of dollars for high-speed access to its collections and offered Nvidia approximately 500 terabytes of data, including millions of books typically available through Internet Archive's digital lending system3
4
.
Source: PC Gamer
Competitive pressures and broader copyright infringement allegations
The complaint asserts that "competitive pressures drove NVIDIA to piracy," highlighting the intense race among AI companies to secure vast training datasets
3
4
. Nvidia develops its own AI models, including NeMo, Retro-48B, InstructRetro, and Megatron, which require massive text libraries for training3
. Beyond Anna's Archive, Nvidia also faces accusations of using other pirated sources, including LibGen, Sci-Hub, and Z-Library, in addition to the Books3 database3
. The lawsuit further alleges that Nvidia distributed scripts and tools enabling corporate customers to download The Pile, which contains the Books3 pirated dataset, introducing new claims of vicarious infringement and contributory infringement3
.
Source: Tom's Hardware
Related Stories

Industry-wide pattern of training AI with pirated data
Nvidia isn't alone in facing scrutiny over data sourcing practices. Meta and Anthropic have previously been found using pirated content from Books3 for their language models
1
2
. However, this marks the first public disclosure of correspondence between a major U.S. tech company and Anna's Archive3
. In a previous case against Anthropic, a court judge ruled that while accessing the data did fall under fair use, "Anthropic had no entitlement to use pirated copies for its central library"2
. Nvidia has defended its actions under fair use, arguing that "training measures statistical correlations in the aggregate, across a vast body of data" and that books represent mere statistical correlations to its AI models2
3
.What this means for intellectual property rights and AI development
The evidence presented during the discovery phase of this class-action lawsuit raises critical questions about how AI companies balance innovation with intellectual property rights. These court documents appear to show that super-wealthy firms jealously guard their own technologies while showing little regard for the intellectual property of others
1
. The authors seek compensation for damages, and hundreds of other authors whose work appears in the massive pirate library may later join the class-action lawsuit1
3
. The complaint does not explicitly state whether Nvidia followed through with paying for access to the dataset or if the deal was ultimately completed3
4
. As this case progresses, it may set precedents for how courts interpret fair use in the context of AI training and whether companies can legally leverage illegally obtained data for commercial AI development.References
Summarized by

Navi
[1]
Related Stories
Meta Faces Legal Challenges Over Alleged Use of Pirated Books for AI Training
08 Feb 2025•Technology

Meta Faces Legal Scrutiny Over Alleged Copyright Infringement in AI Training
11 Mar 2025•Policy and Regulation
Adobe faces class-action lawsuit over alleged use of pirated books in AI training
18 Dec 2025•Policy and Regulation

Recent Highlights
1
AI Hallucination Nearly Sparked US Military Confrontation With Chinese Ship in Middle East
Technology

2
Google Gemini Hacked Three Real Companies During Cybersecurity Testing, Raising AI Safety Concerns
Technology

3
OpenAI Claims AI Breakthrough on Navier-Stokes Problem, Sparking Math Community Crisis
Science and Research

Recent Highlights
Today's Top Stories






Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


