A jailbroken PS4 now runs a modern AI model, no PC or internet needed


2 Sources
[1]
Jailbroken PS4 runs 9-billion-parameter AI model at up to 43 tokens per second -- open-source Garlic LLM bypasses drivers to talk directly to the 2013-era GPU
It needs no PC and no internet, just a console running GoldHEN. Developer Leonardo Alegría's open-source project Garlic LLM lets a jailbroken PS4 run the 9-billion-parameter Qwen3.5-9B AI model offline on the console's 2013-era GPU. The app talks to the GPU directly, and the model is shrunk to
[2]
Jailbroken PS4 runs a 9-billion-parameter AI model at up to 43 tokens per second
Garlic LLM runs Alibaba's Qwen3.5-9B offline on the PS4 using custom GPU code, fitting the massive AI model into just 8GB of shared memory. A developer ran a 9-billion-parameter AI model locally on a jailbroken PlayStation 4, reaching speeds of up to 43 tokens per second. The project called Garlic
Share
Copy Link
A jailbroken PlayStation 4 can now run a modern large language model entirely offline, with no separate computer or internet connection, using a free open-source app called Garlic LLM from developer Leonardo Alegría
1
2
.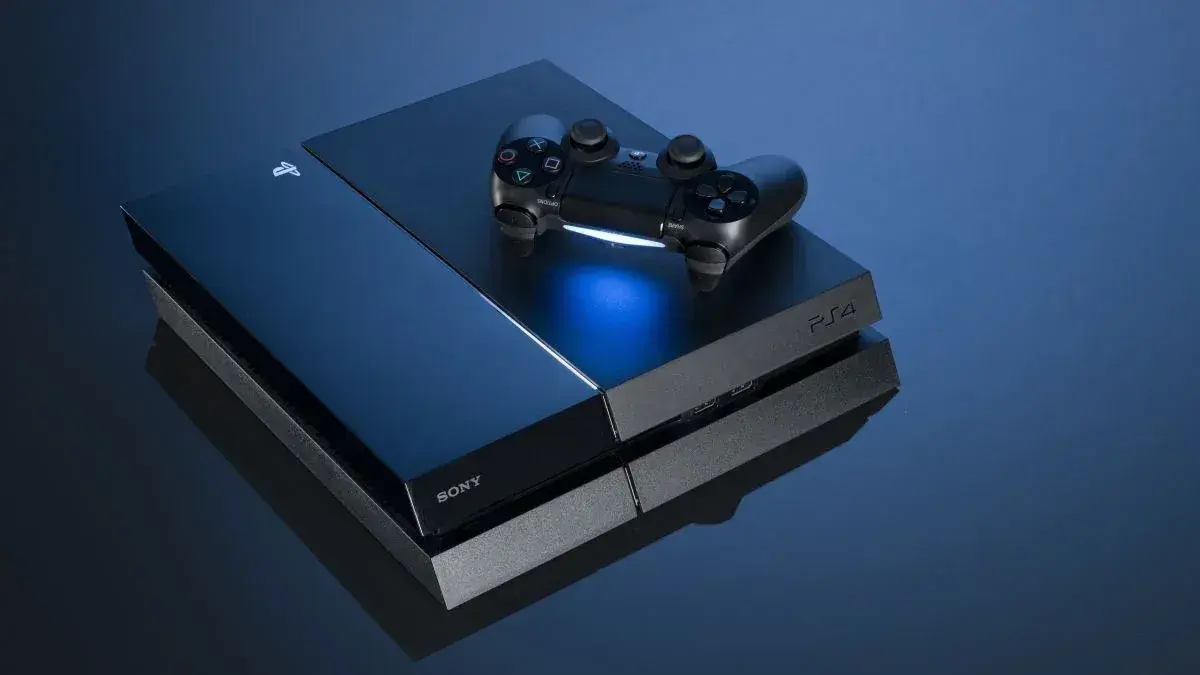
Source: TweakTown
The model is Qwen3.5-9B, Alibaba's small open-weight model with 9 billion parameters, and it runs on console hardware from 2013.
How it fits, and how it's fast
Squeezing the model down is what makes the whole thing possible: at full precision the model is estimated to need more memory than the console's 8GB of shared memory. Alegría quantized it with mixed 3-bit and 4-bit weights, a compression method that trades some precision for size, shrinking it to about 4.5GiB
1
2
. The context window, the amount of text the model can consider at once, is cut to 16K tokens from a native 256K to keep the memory budget workable1
.In text chat the model produces 31 to 39 tokens per second, where a token is roughly a word fragment, and up to 43 tokens per second when generating code
1
2
. The project credits that speed to speculative decoding using Qwen3.5's multi-token prediction head, which drafts up to two tokens ahead and has the full model check them1
2
. That matches how Alibaba trained the model.Talking straight to the GPU
The technical trick is the route to the hardware. The PlayStation 4 has no homebrew GPU driver layer, so the developer had to write the low-level pieces from scratch
1
. Garlic LLM skips driver layers altogether1
2
. It uses custom OpenCL C compute kernels, compiled with LLVM for the Graphics Core Next architecture in the console's Radeon GPU, plus hand-built PM4 command buffers1
2
. Neither the standard llama.cpp tooling nor a Vulkan port is involved1
2
.The closest prior project is PS5LM, a fork that ran Qwen3.8-27B, a model three times larger, at around 20 tokens per second on a PlayStation 5
1
. It took a different road, though: standard llama.cpp code over a Vulkan driver port1
.Related Stories
What you need to run it
The app needs a jailbroken console running GoldHEN, a homebrew enabler; it contains no exploit itself, and installing GoldHEN is at the user's own risk. It was tested on firmware 11.52
1
2
. The download is free, 5.66GB on Hugging Face, installed through the PS4 Package Installer with about 6GB of free space needed1
2
.Beyond text, it handles voice conversation in seven languages using the Chatterbox speech model, and chat speed drops to about 22 tokens per second while speech runs
1
2
. Dictation runs via Nvidia's Parakeet model, which covers 25 European languages1
2
.The catch is that every performance figure comes from the developer's own testing and user reports, and the test prompt and method have not been published
1
2
. The developer has not tested the PlayStation 4 Pro, and the PlayStation 5 is not supported; the app targets the PlayStation 4's GPU and system software specifically1
. The developer's website lists user-reported PlayStation 4 Pro results of up to 56 tokens per second through an experimental native mode, and he is asking owners to post their own numbers on GitHub2
.References
Summarized by

Navi
[1]
Related Stories
Jailbroken PS5 Now Runs Local AI Models at 124 Tokens Per Second Using Native GPU Access
16 Oct 2026•Technology
OpenAI's GPT-5 and GPT-OSS Models Jailbroken Within Hours of Release
07 Aug 2025•Technology
Sony's AI Innovation: Custom Hardware and Collaboration with AMD for Next-Gen Gaming Graphics
19 Dec 2024•Technology

Recent Highlights


Recent Highlights
Today's Top Stories










Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


