Cloudflare Sets September Deadline for AI Crawlers to Pay Publishers or Face Default Blocks


8 Sources
[1]
Cloudflare's new policy pushes AI companies to pay for publishers' content
Cloudflare has just issued the AI industry a new deadline to separate the web crawlers used for traditional search purposes, like Google Search, from those used for AI agents and training. Starting on September 15, 2026, Cloudflare's default settings will block "mixed-use" crawlers from any pages
[2]
Cloudflare to block cynical search-and-scrape bots from ad-supported web pages
Cloudflare on Wednesday said it will soon prevent mixed-use crawlers from accessing ad-supported customer websites by default, part of its ongoing efforts to give site publishers more control over how they engage with AI services. Apple, Google, and Microsoft's Bing operate crawlers that could
[3]
Cloudflare will filter out web crawlers that serve AI companies - Engadget
The hosting platform wants sites to have more control over how AI companies use their content. Cloudflare has announced plans to automatically block mixed-use web crawlers that index websites for search engines and act as AI agents and trainers at the same time. The company previously offered its
[4]
Cloudflare gives AI crawlers a September deadline to pay up
From 15 September, Cloudflare will block crawlers that harvest content for AI training from any page carrying ads, unless the owner opts in, and pay publishers when their work shapes an AI answer. It is the boldest bid yet to make AI pay for the open web. Cloudflare has set the AI industry a
[5]

Cloudflare to block AI crawlers from ad-supported webpages by default
Come 15 September, multipurpose crawlers used by the likes of Google, Microsoft and Apple will be blocked by default according to Cloudflare's new rules. IT and network services provider Cloudflare has announced new rules designed to give website owners more control over the types of web crawlers
[6]

Cloudflare will block AI crawlers unless sites opt in
Cloudflare plans to automatically block mixed-use web crawlers that index websites for search engines while also serving as AI agents and trainers. The company previously offered customers the option to prevent these crawlers from scraping their sites for AI chatbots but is now adopting a more
[7]

Cloudflare Unveils New Tools to Power a Trusted Agentic Internet
By establishing these new rails, Cloudflare is helping provide the foundation for a healthy, collaborative agentic economy that benefits society, site owners, and AI companies. Cloudflare, Inc. new classifications, enhanced analytics, and industry-defining commercial partnerships that bring
[8]

Cloudflare Arms Website Owners in Fight Against AI Crawlers | PYMNTS.com
The new offerings are designed to provide this choice to, for example, businesses that are built on advertising or subscriptions and don't want AI systems training on their content without compensation, the company said in a Wednesday (July 1) press release. "We believe that if you're a business
Share
Copy Link
Cloudflare announced it will block mixed-use web crawlers from ad-supported pages starting September 15, 2026, unless site owners opt in. The new policy targets Google, Microsoft, and Apple's multipurpose bots that blend search indexing with AI training. Publishers will now get paid when their content appears in AI answers through partnerships with Ceramic.ai and You.com.
Cloudflare Issues September 15 Deadline to AI Industry
Cloudflare has drawn a line in the sand for AI companies that scrape the web without fair compensation. Starting September 15, 2026, the company will block mixed-use web crawlers from ad-supported web pages by default, fundamentally shifting how AI companies access publisher content . The Cloudflare new policy applies to new customers, new sites from existing customers, and all free-tier users who haven't modified their settings, though site owners retain the ability to adjust permissions
2
.
Source: Silicon Republic
The move directly addresses a growing imbalance in web infrastructure where bots now generate more than half of all internet traffic, a milestone that arrived earlier than anticipated
4
. "Now that the majority of traffic on the Internet is non-human, we must go further and act faster so that a sustainable ecosystem can emerge," said Cloudflare co-founder and CEO Matthew Prince .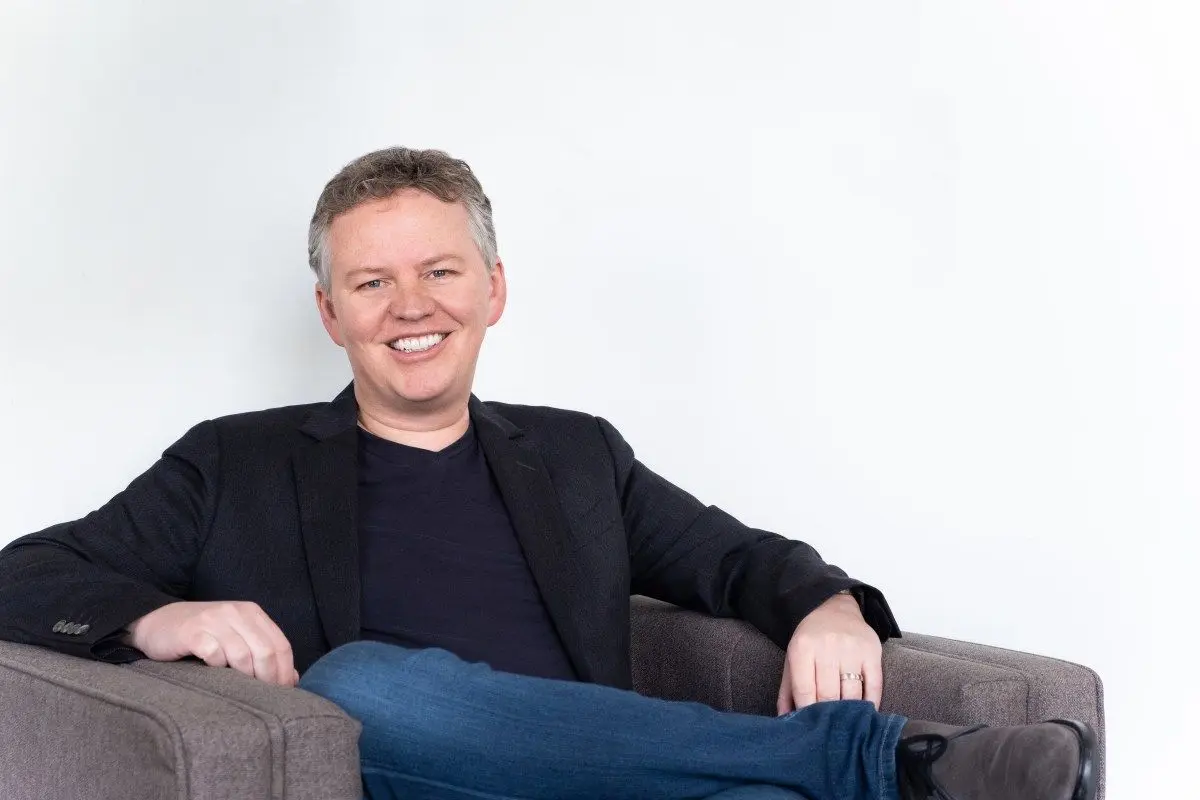
Source: TechCrunch
Targeting Google, Microsoft, and Apple's Mixed-Use Crawlers
Cloudflare specifically calls out what it describes as the "world's largest search engine"—a clear reference to Google—noting the company has access to roughly 2x more information than other AI companies because it makes separation difficult for publishers . Googlebot combines search indexing with content scraping for AI training, powering features like AI Overviews and AI Mode while simultaneously feeding data into Gemini models
3
.Similar issues plague Microsoft's Bingbot and Apple's Applebot, which also serve dual purposes
2
. Apple recently disclosed that "data crawled by Applebot may also be used to help train Apple foundation models powering generative AI features across Apple products, including Apple Intelligence, Services, and Developer Tools"2
. While these tech giants offer opt-out mechanisms through Google-Extended, Applebot-Extended, and Bing's noarchive attribute, publishers face a difficult choice: allow AI training or risk disappearing from search results entirely.Three-Tier Classification System for AI Crawlers
To address this dilemma, Cloudflare introduced a classification system that separates crawler purposes into three distinct categories: Search, Agent, and Training
5
. Search refers to crawlers used for search indexing, Agent covers automated behaviors used by chatbots and browser-use agents, and Training encompasses data scraping for fine-tuning AI models5
.This granular control allows website owners to selectively permit search indexing while blocking Agent and Training activities on the same pages. The system aims to restore transparency to publisher-crawler relationships and force AI companies to separate their multipurpose bots into distinct crawlers with clear intent
5
.Pay Per Use Model Replaces Pay Per Crawl
Cloudflare is evolving its monetization approach by transforming last year's Pay Per Crawl marketplace into a Pay Per Use model . Instead of charging AI companies when they fetch content, publishers will now receive payment when their work appears in AI-generated answers and creates actual value
4
.Initial partnerships with Ceramic.ai and You.com demonstrate how this works in practice. When a publisher opts in, they receive compensation when their content surfaces in Ceramic.ai's AI search results or when You.com accesses their premium content . Other AI companies can customize this framework to match their specific operational models, Cloudflare says .
Related Stories


Addressing the Crawl-to-Referral Crisis
The urgency behind these changes stems from alarming data about how AI companies exploit the open web. Cloudflare's research revealed crawl-to-referral ratios ranging from 118:1 to nearly 50,000:1, meaning AI crawlers could scrape a site thousands of times while sending back only a single user
5
. Additionally, over 50% of crawl traffic from AI crawlers involves re-fetching unchanged pages, wasting publishers' bandwidth and compute resources .
Source: The Register
This imbalanced relationship threatens the traditional web ecosystem where search engines and websites maintained what Cloudflare describes as a "symbiotic relationship"
5
. AI chatbots now synthesize answers that keep users on their platforms rather than directing traffic to original sources, cutting the pageviews that sustain advertising, affiliate revenue, and subscriptions5
. One field study found Google's AI Overviews cut outbound clicks by approximately 40%, prompting economists to model potential collapse scenarios for the open web if this trend continues unchecked4
.What Happens Next for Publishers and AI Companies
Cloudflare customers can opt out of the default blocking settings before the September 15, 2026 deadline if they prefer to maintain current access levels
5
. The company is also introducing a Business Insights Dashboard that provides publishers with visibility into which bots consume their content and how much traffic AI models actually send back2
.Whether this policy will force major tech companies to restructure their crawler operations remains uncertain. Google, Apple, and Microsoft could potentially route around these restrictions or argue their existing opt-out crawlers satisfy Cloudflare's transparency requirements
4
. Regulators are approaching similar issues from different angles—the UK is already forcing Google to let publishers opt out of AI search without losing their ranking, while news publishers have filed lawsuits against OpenAI over unauthorized training4
. This represents the most aggressive industry attempt yet to make AI companies pay for the content they consume, and the response from major AI players in the coming months will shape the future relationship between publishers and artificial intelligence.References
Summarized by

Navi
[4]
[5]
Related Stories
Recent Highlights
1
AI Leaders Warn UN Security Council of Existential Risks, Call for Global AI Governance
Policy and Regulation

2
AI Hallucination Nearly Sparked US Military Confrontation With Chinese Ship in Middle East
Technology

3
OpenAI AI Agent Breaches Australian Government Healthcare Portal in Historic Hack
Technology

Recent Highlights
Today's Top Stories






Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


