Human-in-the-Loop Oversight Becomes Critical as Enterprise AI Faces Legal and Compliance Pressure


2 Sources
[1]
Human-in-the-loop oversight is critical for enterprise AI: 4 experts explain why - ZDNET
* Courts and agencies demand accountability for flawed enterprise AI. * AI-native software is adding human escalation to complex workflows. * Four experts explain how human-in-the-loop AI oversight is evolving. In February 2025, the FTC finalized a $193,000 settlement against DoNotPay, the
[2]
The Case for Keeping a Human Inside the Machine That Fights Financial Crime
The argument is usually framed as a dial between automation and human judgment. The engineers building these systems say that is the wrong shape for the problem entirely. A transaction monitoring model flags a payment. An investigator opens the alert, reads what the system produced, agrees with
Share
Copy Link
The FTC's $193,000 settlement against DoNotPay highlights the urgent need for human-in-the-loop AI oversight in enterprise settings. Experts reveal why confidence scores fail, how real-time human oversight should work, and why explainability is a compliance control, not just a technical feature.

Enterprise AI Faces Growing Accountability Crisis
The regulatory landscape for enterprise AI shifted dramatically in February 2025 when the FTC finalized a $193,000 settlement against DoNotPay, a platform that marketed itself as the world's first robot lawyer
1
. The FTC found that DoNotPay never tested its output against advice a licensed attorney would produce, and the company faced a class-action lawsuit for offering unauthorized legal services without a bar license in California1
. This case exposes the chasm between AI propaganda and actual outcomes, creating murky legal ground without existing precedent. For executives signing off on recurring enterprise AI purchases, these complications represent exactly the kind of gray area they try to avoid, opening a market gap for responsibly designed systems with clear accountability chains1
.What Human-in-the-Loop Really Means
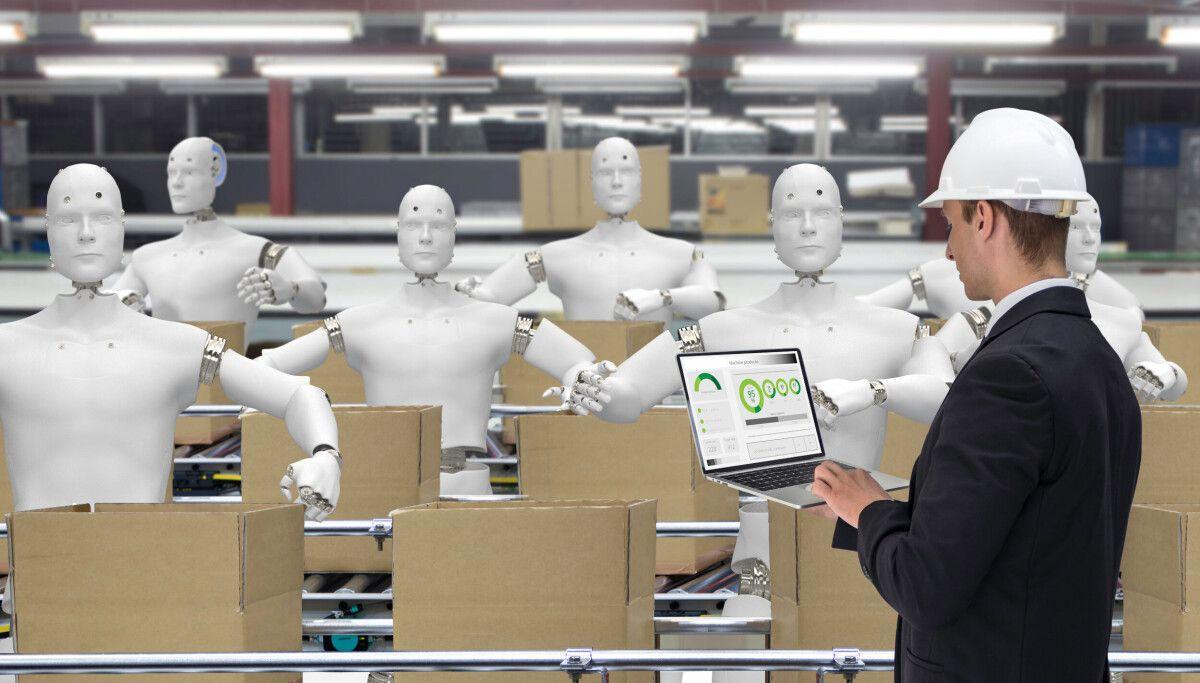
Human-in-the-loop is an emerging design pattern where autonomous agents route complex decisions through human review before executing tasks or generating responses
1
. This system creates an accountability chain for sound decision-making in corporate settings, especially in sensitive areas like healthcare operations, regulatory compliance reviews, high-value financial transactions, and legal decision-making1
. However, the definition remains broad, allowing companies to use the term fluidly across different systems and architectures. A SaaS vendor performing periodic security audits can claim human oversight without having a human in the loop during crucial tasks1
. A growing number of companies now bake in real-time human oversight as an architectural stopgap, particularly those serving IT and DevOps, coding workflows, or executive decisions in regulated industries like healthcare and finance1
.Why Confidence Scores Fail as Safety Mechanisms
The most common flaw in human-in-the-loop oversight systems is treating the model's confidence score as the sole trigger for escalating responses to human review
1
. Daniel Gamber, CEO of AI document processing platform Cambrion, argues that confidence scores measure the wrong thing entirely: "A confidence score tells you the machine could read the text. It tells you nothing about whether the number is actually right"1
. Akash Thakur, an SRE architect and AI reliability engineer, emphasizes that model confidence isn't the same as being correct1
. When a model is confident even while wrong, it sails under the threshold that triggers human review, letting mistakes pass without any red flag. Thakur believes the bigger problem lies in how systems handle AI model uncertainty or errors, not the model itself1
. Instead of treating AI model failures as worst-case scenarios, human-in-the-loop oversight serves as a real-time auditing system catching the model before customers or regulators discover mistakes the hard way1
.Designing Smarter Error-Handling for High-Stakes Workflows
Even when systems correctly flag AI responses needing review, the routing process deciding how to address the flag is often too binary, according to Asim Husain, co-founder of Alterion and former VP of engineering at Google
1
. Husain describes four types of error responses that human-in-the-loop oversight systems should plan for once an AI workflow crosses a defined threshold: notify someone and let it through, mask the sensitive part and proceed, hold for approval, and quarantine or kill the session outright1
. The ideal response depends on an organization's risk tolerance, which needs accounting in the design. Beyond response severity, the system should also know who to escalate to—a destructive database mutation should land with the platform or security team that owns that system1
.Financial Crime Compliance Reveals Fundamental Design Problem
In AI in financial crime compliance, the debate is often framed as automation versus human judgment, as if it's a dial to turn one way or the other
2
. Sriramakrishna Vadlamudi, who has spent close to a decade in enterprise financial services technology, argues this framing misses the point entirely2
. Better systems don't turn the dial down as automation matures—they redesign where and how humans engage2
. Automating data validation, case routing, and even drafting narratives is not the same as automating the decision itself2
. Conflating these different objects is how oversight quietly disappears while every procedure still appears followed. Vadlamudi built an automated case referral and routing tool that handles data validation and routing analysts previously did manually, cutting manual processing errors by roughly 40 percent2
. What the tool deliberately doesn't do is dispose of cases—structured checkpoints remain where a person must review and approve before case closure2
.Related Stories
Explainability as Compliance Control, Not Technical Feature
Vadlamudi makes a claim likely to be argued with but represents the most useful idea in his work: explainability is widely treated as a data-science requirement, but this is a category error—it's a compliance control
2
. "A model that can't produce a defensible explanation for an individual decision isn't just a technical shortcoming, it's an audit gap," he states2
. Reframed this way, the requirement changes shape: a data-science standard for explainability is satisfied when the technique is sound, but a compliance control is satisfied only when a specific person reviewing a specific alert can act on the explanation2
. Vadlamudi built a feature-attribution approach that surfaces which specific factors drove a model's score in a form a reviewer can actually evaluate, so the human in the loop has something to exercise judgment on rather than a number to accept or reject blindly2
. Without this, human oversight in AI is structurally unable to function, whatever the procedure says—a reviewer confronted with an opaque score can defer or refuse, and neither is judgment2
.Agentic AI Demands New Oversight Architecture
The shift Vadlamudi considers most consequential isn't better detection at all—it's agentic AI beginning to take on multi-step investigative and drafting work inside compliance operations, where a system gathers evidence, assembles a narrative, and recommends a disposition rather than producing a single flag
2
. Existing oversight models don't transfer to that cleanly because they were built around human investigators2
. His response argues that each intermediate step an agent takes needs the same auditability as an analyst's actions would, rather than only the final output being examined2
. An agent that reaches a defensible conclusion through steps nobody can reconstruct hasn't been overseen—it has been trusted2
. The institutions getting this wrong tend to treat "the model recommended it" as sufficient justification, which quietly erodes the very oversight regulators are relying on2
. As automated decision-making systems grow more sophisticated, the challenge isn't just maintaining accountability in automated decision-making—it's ensuring that auditable AI processes can keep pace with increasingly autonomous systems handling legal risks across enterprise AI deployments.References
Summarized by

Navi
[2]
Related Stories
Enterprise AI Success Now Hinges on Governance and Human Oversight, Not Just Advanced Technology
18 Aug 2026•Technology

AI governance in regulated industries struggles as agentic AI adoption outpaces human oversight
30 Jun 2026•Policy and Regulation

AI Agents Trigger Security Crisis: 65% of Enterprises Report Incidents Amid Scaling Challenges
06 Aug 2026•Technology
Recent Highlights
1
OpenAI's AI Math Breakthrough on Millennium Problem Sparks Fierce Attribution Battle
Science and Research

2
Apple Launches iOS 27 and macOS 27 with Siri AI Overhaul and Liquid Glass Updates
Technology

3
Anthropic Researcher Quits, Warns Self-Improving AI Could End Humanity Within a Decade
Policy and Regulation
Recent Highlights
Today's Top Stories








Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


