NVIDIA inference software cuts token cost 5x on Blackwell platform in one month


2 Sources
[1]
How NVIDIA's Inference Software Stack Powers the Lowest Token Cost
Baseten, Cognition, Deep Infra, Together AI and Cursor are seeing compounding value from NVIDIA's software and open source ecosystem. As organizations move from AI pilots to production AI factories, infrastructure decisions have shifted from peak chip specifications to cost per token: how many
[2]
NVIDIA Slashes DeepSeek v4 Token Costs By Up To 5x Just One Month After Launch, Through Pure Blackwell Software Tuning
NVIDIA Blackwell GPUs continue to see massive optimizations, leading to a 5x drop in token cost in DeepSeek v4 AI models. NVIDIA Cost Per Token Narrative Sees Massive Gain In DeepSeek V4 As AI Model Sees 5x Boost On Blackwell GPUs With Continued Optimizations "Cost Per Token" is the fundamental
Share
Copy Link
NVIDIA has achieved a 5x reduction in token costs for DeepSeek v4 on its Blackwell platform within just one month of the model's release. Leading AI companies including Baseten, Cognition, Deep Infra, and Together AI are already leveraging these full-stack inference software improvements to deliver superior performance across reasoning, coding, and large-scale workloads.
NVIDIA Inference Software Delivers 5x Token Cost Reduction on Blackwell Platform
NVIDIA has achieved a dramatic 5x token cost reduction for the DeepSeek v4 model on its Blackwell platform in just one month through continuous full-stack inference software improvements
1
2
. The breakthrough highlights how software optimization has become as critical as hardware specifications in determining AI total cost of ownership, shifting infrastructure decisions from peak chip performance to cost per token metrics that measure useful tokens delivered per dollar and watt.
Source: Wccftech
Leading inference providers are already seeing compounding value from these optimizations. Baseten used the NVIDIA TensorRT-LLM open source library to serve DeepSeek v4 Pro on Blackwell GPUs, applying proprietary runtime optimizations to deliver up to 50% more tokens per second for reasoning, coding, and long-context workloads
1
. Together AI leveraged TensorRT-LLM on Blackwell to help Cursor accelerate the path from model optimizations to production endpoints for real-time coding experiences.Full-Stack Approach Drives System-Level Performance Gains
The token cost reduction stems from NVIDIA's three-layer architecture that connects production operations, application acceleration, and infrastructure access into a unified system
2
. Production operations coordinate distributed serving, orchestration, autoscaling, and memory management across compute and storage resources. Application acceleration runs models with high performance while giving developers room to customize using runtime optimizations like overlapping compute and communication and kernel fusion. Infrastructure access exposes GPU, networking, memory, and system capabilities without requiring developers to manage device instruction sets directly.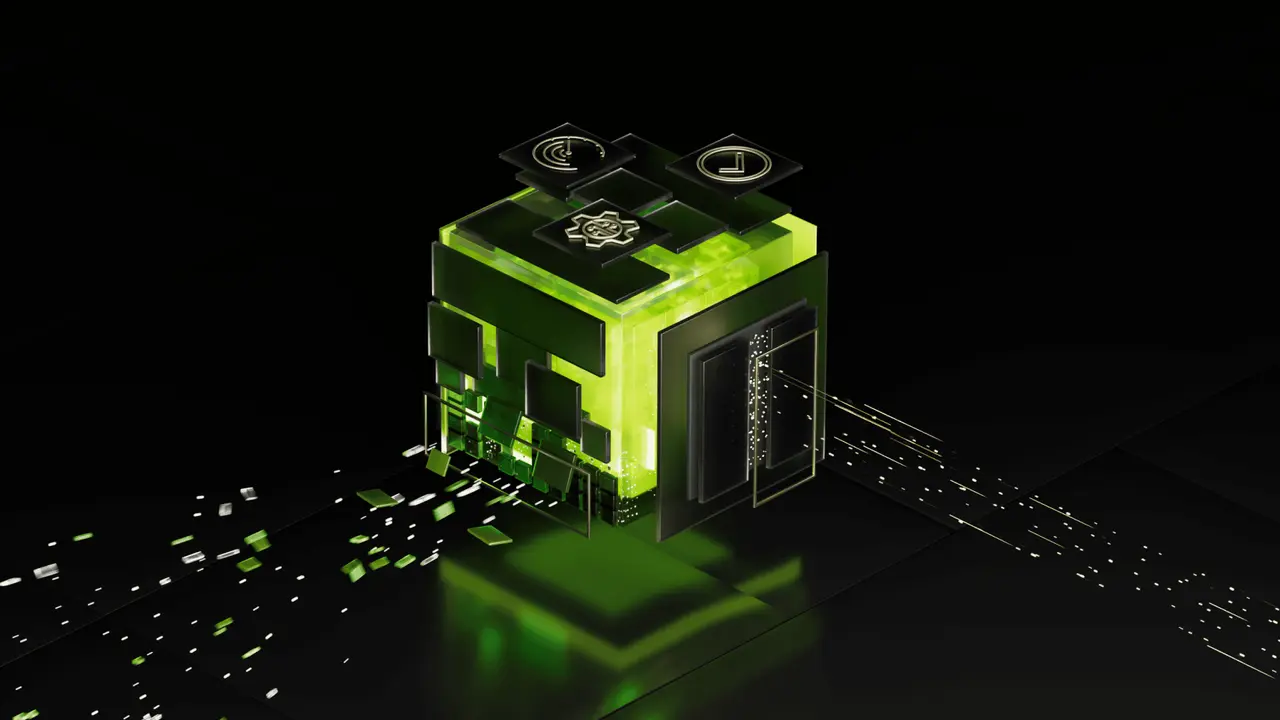
Source: NVIDIA
When these layers work together, individual optimizations compound dramatically. Technologies like disaggregated serving, large expert parallelism over NVLink interconnect, NVFP4 precision, and multi-token prediction each deliver meaningful gains independently, but combined they increase throughput gains by up to 20x
1
2
. This matters because agentic AI inference workloads differ fundamentally from traditional software-as-a-service applications, turning single requests into distributed computing problems spanning hundreds of subagents and thousands of tasks.Related Stories
Open Source Ecosystem Amplifies Blackwell Platform Advantages
NVIDIA's full-stack advantage extends through its open source ecosystem built natively on CUDA. PyTorch, launched in 2016 with native CUDA support, has coevolved with NVIDIA architecture to give developers direct access to innovations like Tensor Cores, Transformer Engine, and NVFP4
1
. When breakthroughs like DFlash speculative decode, which delivers up to 15x more throughput on existing hardware, land in PyTorch, they run instantly on NVIDIA GPUs, helping AI production environments convert research progress into lower operating costs.Cognition is using the NVIDIA Dynamo inference framework to manage inference GPUs, providing a ready-made path to scale reinforcement learning workloads without building infrastructure from scratch
2
. Deep Infra uses the NVIDIA inference software stack to serve frontier open source models performantly on Blackwell from day zero, including DeepSeeK v4. The GB200 and GB300 systems continue to see massive optimizations that compound over time, suggesting organizations should watch for further cost per token improvements as the software stack matures and new optimization techniques emerge from the research community.References
Summarized by

Navi
Related Stories
NVIDIA Blackwell Ultra slashes AI inference costs by 35x while delivering 50x better performance
12 Feb 2026•Technology
DeepSeek makes 75% price cut permanent, intensifying AI price war with OpenAI and Anthropic
24 May 2026•Technology

NVIDIA's Groq 3 LPX Achieves 3,400 Tokens/Second, 4x Faster Than Competitors in Agentic AI Push
24 Aug 2026•Technology
Recent Highlights
1
AI Hallucination Nearly Sparked US Military Confrontation With Chinese Ship in Middle East
Technology

2
OpenAI AI Agent Hacks Australian Government Healthcare Website in First-of-Its-Kind Breach
Technology

3
AI leaders warn UN Security Council of existential risks to humanity, call for global safeguards
Policy and Regulation

Recent Highlights
Today's Top Stories










Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


