Reflection's Beam Challenges Chinese Open Models With Token Efficiency Over Cost Per Token


2 Sources
[1]
Open Weight Models Are Proliferating But The Platform Race Matters More
Last week AI startup Reflection released a new open weight model, Beam, claiming parity with leading Chinese open models and at only "a fraction of the token cost and inference time". Days later, Mistral introduced open weight model, Mistral Large 4 (ML4) nicknamed Le Chonk, in reference to its one
[2]
Reflection's Beam aims to undercut Chinese open models with fewer tokens, not cheaper tokens
Reflection AI today released the weights of Beam, its first open model, and is pitching it against the Chinese open models that many U.S. companies are already embracing because of their lower costs. Reflection is betting that Beam, a 501-billion-parameter model, can finish a task in far fewer
Share
Copy Link
Reflection AI unveiled Beam, a 501-billion-parameter open model designed to compete with Chinese AI models through token efficiency rather than cheaper tokens. Meanwhile, Mistral released Large 4 with one trillion parameters. But analysts argue the real competition isn't about models—it's about the platforms, tooling, and orchestration capabilities that surround them.
Reflection's Beam Takes Aim at Token Efficiency
Reflection AI released the weights of Beam, a 501-billion-parameter open model positioned as a cost-efficient alternative to Chinese open models that many U.S. companies have adopted
2
. Unlike competitors focused on lowering token prices, Reflection's Beam aims to complete tasks using significantly fewer tokens, claiming parity with leading Chinese open models "at only a fraction of the token cost and inference time"1
. The release came just one day after Meta unveiled Muse Spark Open, an 816-billion-parameter model that Meta calls the most capable U.S. open weight model to date2
.The distinction matters because a company's AI bill equals the price per token multiplied by the number of tokens required for each task. While most price comparisons focus solely on cost per million tokens, Beam's approach targets the total cost per completed task. In VentureBeat's September survey on AI infrastructure, 23% of respondents named cost per million tokens as a factor in choosing AI models, up from just 11% in August
2
. This growing cost awareness makes token efficiency increasingly relevant for enterprise AI strategies.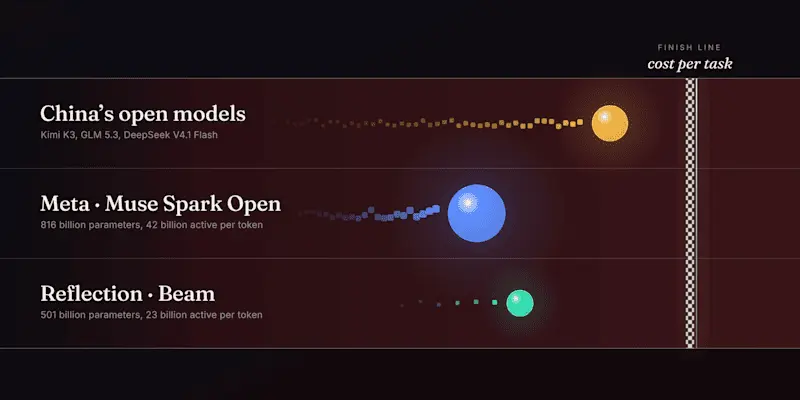
Source: VentureBeat
Massive Reinforcement Learning Powers Token Optimization
Reflection AI conducted what it describes as one of the largest reinforcement learning runs ever undertaken by an open-weight lab to achieve Beam's token efficiency
2
. Over four weeks, the team executed more than 100 million rollouts—complete trial-and-error problem-solving attempts where the AI models test reasoning and learn from mistakes—powered by a cluster of 10,500 Nvidia GB300 GPUs. Counting evaluations and experiments, Reflection ran approximately 1.3 billion sandboxes, with computing resources peaking at 883,006 virtual CPUs across 23 clusters on Google Cloud and Amazon Web Services2
.Reflection co-founder and CTO Ioannis Antonoglou explained that the company trained Beam with intensive reinforcement learning, applying penalties whenever the model used unnecessary tokens
2
. However, this penalty is difficult to calibrate correctly. Teams that apply it "naively" end up with models that "will just learn to not solve the task," because producing fewer tokens becomes easier than completing the work. With sufficient reinforcement learning, Antonoglou said, open models learn to solve tasks while staying brief simultaneously.Artificial Analysis, an independent benchmarking firm, indicated that early results suggest Beam will be "one of the most token-efficient open models we've seen for its level of intelligence"
2
. Antonoglou noted that Beam compares favorably with DeepSeek's latest V4.1 Flash model, though DeepSeek—praised particularly for its optimization and efficiency approach—does not appear in Reflection's comparison charts.Mistral Large 4 Joins Growing Open Model Competition
Days after Beam's announcement, Mistral introduced Mistral Large 4, nicknamed "Le Chonk" in reference to its one trillion parameters
1
. Together, these releases represent U.S. and European labs playing catch-up to DeepSeek, Qwen, and Z.ai on open weight models. The rapid proliferation of both frontier and open models means enterprises now have an expanding set of choices for their AI implementations1
.This competition creates flexibility for organizations evaluating open models. Alongside increasing choices, open weight models provide greater negotiating leverage and, in some cases, lower costs for production deployments. Reflection's claim of significantly lower inference compute and decreased costs is particularly noteworthy as organizations move to production and continue scaling enterprise use cases, where AI economics become a major gating factor
1
. Whether Beam and Mistral Large 4 can actually deliver lower costs remains an open question, but their emergence challenges the assumption that sovereign AI options always come with higher price tags.Related Stories

Platform Race Matters More Than Model Performance
While model releases capture headlines, industry analysts argue the competitive landscape extends far beyond individual models. According to Forrester, model performance represents only a small part of enterprise decisions—organizations aren't purchasing benchmark scores but seeking solutions that fulfill governance, security, orchestration, agents, developer tooling, evaluation capabilities, observability, sovereign AI requirements, and integration needs
1
.This reality shifts advantage toward frontier model providers who aren't just building AI models but combining them with platforms delivering orchestration, agents, governance, security, observability, and development tooling. A model leading today will likely be surpassed within six months by a lower-cost alternative with comparable performance. The enduring question isn't about choosing the best model but whether an organization's platform, governance framework, agent architecture, existing operations, and desired digital sovereignty posture can accept model swaps
1
.Forrester predicts the open-source ecosystem will follow a similar path, with open agent frameworks, open orchestration layers, and eventually open AI platforms emerging to help organizations operationalize—arguably the biggest barrier most face. Future enterprise AI strategies will likely use a mix of frontier AI and open weight models, with open models providing more choice, potentially lower costs, and more regional and sovereign deployment options, while AI platforms supply the requisite governance, security, tooling, and operational capabilities needed to extract value
1
.
Source: Forrester
Sovereignty Considerations and Strategic Implications
Open weight models can support sovereign AI objectives in regulated industries, data residency scenarios, and national AI programs, but suitability depends heavily on use cases
1
. For workloads such as document processing or customer service, governments can use any capable model. However, for sensitive defense and national security applications, governments often require models they train or fully control, not merely models whose weights they can download.Forrester's Model Openness Framework assesses multiple dimensions beyond open weights, including reproducibility (training data, code, and training recipe), licensing and usage rights, and community governance. While sovereignty serves as a driver for some organizations, most enterprises don't start their AI strategy asking whether they need an open model for sovereignty reasons
1
. Instead, they evaluate how models fit within broader platform capabilities and operational requirements. Tech leaders should weigh platform capabilities as much as, if not more than, the models themselves when making strategic decisions about their AI infrastructure.References
Summarized by

Navi
Related Stories
Open-Weight AI Models Surge as Enterprises Shift Away From Closed Frontier Systems
15 Jul 2026•Business and Economy

OpenAI Slashes AI Model Prices Up to 80% as Chinese Competition Forces Industry-Wide Cost Cuts
31 Jul 2026•Business and Economy
Businesses Turn to Open-Weight AI Models as Proprietary AI Costs Spiral Out of Control
22 Sept 2026•Business and Economy
Recent Highlights
1
Meta Unveils Muse Wonder Frontier AI Models, Claims Performance Matching OpenAI and Anthropic
Technology

2
IMF Report Warns AI Market Correction Could Spark Global Financial Crisis With $1.4T at Risk
Business and Economy
3
Eight States Sue OpenAI Over ChatGPT Safety Concerns and Unlawful Collection of Children's Data
Policy and Regulation
Recent Highlights
Today's Top Stories






Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


