Apple Study Challenges AI Reasoning Capabilities, Casting Doubt on AGI Claims


22 Sources
[1]
New Apple study challenges whether AI models truly "reason" through problems
In early June, Apple researchers released a study suggesting that simulated reasoning (SR) models, such as OpenAI's o1 and o3, DeepSeek-R1, and Claude 3.7 Sonnet Thinking, produce outputs consistent with pattern-matching from training data when faced with novel problems requiring systematic
[2]
Is superintelligent AI just around the corner, or just a sci-fi dream?
Tech CEOs are promising increasingly outlandish visions of the 2030s, powered by "superintelligence", but the reality is that even the most advanced AI models can still struggle with simple puzzles If you take the leaders of artificial intelligence companies at their word, their products mean that
[3]
Apple says generative AI cannot think like a human - research paper pours cold water on reasoning models
Apple researchers have tested advanced AI reasoning models -- which are called large reasoning models (LRM) -- in controlled puzzle environments and found that while they outperform 'standard' large language models (LLMs) models on moderately complex tasks, both fail completely as complexity
[4]
Apple AI boffins pour cold water on reasoning models
If you are betting on AGI - artificial general intelligence, the point at which AI models rival human cognition - showing up next year, you may want to adjust your timeline. Apple AI researchers have found that the "thinking" ability of so-called "large reasoning models" collapses when things get
[5]

AI reasoning models aren't as smart as they were cracked up to be, Apple study claims
AI reasoning models could have fundamental limitations in their ability to solve problems. (Image credit: Getty Images) Artificial intelligence (AI) reasoning models aren't as smart as they've been made out to be. In fact, they don't actually reason at all, researchers at Apple say. Reasoning
[6]

AI flunks logic test: Multiple studies reveal illusion of reasoning
Bottom line: More and more AI companies say their models can reason. Two recent studies say otherwise. When asked to show their logic, most models flub the task - proving they're not reasoning so much as rehashing patterns. The result: confident answers, but not intelligent ones. Apple researchers
[7]

Approaching WWDC, Apple researchers dispute claims that AI is capable of reasoning
While Apple has fallen behind the curve in terms of the AI features the company has actually launched, its researchers continue to work at the cutting edge of what's out there. In a new paper, they take issue with claims being made about some of the latest AI models - that they are actually
[8]
New paper pushes back on Apple's LLM 'reasoning collapse' study - 9to5Mac
Apple's recent AI research paper, "The Illusion of Thinking", has been making waves for its blunt conclusion: even the most advanced Large Reasoning Models (LRMs) collapse on complex tasks. But not everyone agrees with that framing. Today, Alex Lawsen, a researcher at Open Philanthropy, published
[9]

Apple Research Questions AI Reasoning Models Just Days Before WWDC
A newly published Apple Machine Learning Research study has challenged the prevailing narrative around AI "reasoning" large-language models like OpenAI's o1 and Claude's thinking variants, revealing fundamental limitations that suggest these systems aren't truly reasoning at all. For the study,
[10]

'The illusion of thinking': Apple research finds AI models collapse and give up with hard puzzles
New artificial intelligence research from Apple shows AI reasoning models may not be "thinking" so well after all. According to a paper published just days before Apple's WWDC event, large reasoning models (LRMs) -- like OpenAI o1 and o3, DeepSeek R1, Claude 3.7 Sonnet Thinking, and Google Gemini
[11]

Cutting-edge AI models 'collapse' in face of complex problems, Apple study finds
'Pretty devastating' paper raises doubts about race to reach stage of AI at which systems match human intelligence Apple researchers have found "fundamental limitations" in cutting-edge artificial intelligence models, in a paper raising doubts about the technology industry's race to develop ever
[12]
When billion-dollar AIs break down over puzzles a child can do, it's time to rethink the hype | Gary Marcus
The tech world is reeling from a paper that shows the powers of a new generation of AI have been wildly oversold A research paper by Apple has taken the tech world by storm, all but eviscerating the popular notion that large language models (LLMs, and their newest variant, LRMs, large reasoning
[13]

Do reasoning models really "think" or not? Apple research sparks lively debate, response
Join the event trusted by enterprise leaders for nearly two decades. VB Transform brings together the people building real enterprise AI strategy. Learn more Apple's machine-learning group set off a rhetorical firestorm earlier this month with its release of "The Illusion of Thinking," a 53-page
[14]

Apple Researchers Just Released a Damning Paper That Pours Water on the Entire AI Industry
Researchers at Apple have released an eyebrow-raising paper that throws cold water on the "reasoning" capabilities of the latest, most powerful large language models. In the paper, a team of machine learning experts makes the case that the AI industry is grossly overstating the ability of its top
[15]
Frontier AI Models Are Getting Stumped by a Simple Children's Game
Earlier this week, researchers at Apple released a damning paper, criticizing the AI industry for vastly overstating the ability of its top AI models to reason or "think." The team found that the models including OpenAI's o3, Anthropic's Claude 3.7, and Google's Gemini were stumped by even the
[16]

Apple Says Claude, DeepSeek-R1, and o3-mini Can't Really Reason | AIM
The researchers argue that traditional benchmarks, like math and coding tests, are flawed due to "data contamination" and fail to reveal how these models actually "think". AI critic Gary Marcus is smiling again, thanks to Apple. In a new paper titled The Illusion of Thinking, researchers from the
[17]

AI models still far from AGI-level reasoning: Apple researchers
Current "thinking" AI models still can't reason to a level that would be expected from humanlike artificial general intelligence, the researchers found. The race to develop artificial general intelligence (AGI) still has a long way to run, according to Apple researchers who found that leading AI
[18]

Apple's quiet AI lab reveals how large models fake thinking
The latest generation of AI models, often called large reasoning models (LRMs), has dazzled the world with its ability to "think." Before giving an answer, these models produce long, detailed chains of thought, seemingly reasoning their way through complex problems. This has led many to believe we
[19]

Apple Researchers Find 'Accuracy Collapse' Problem in AI Reasoning Models
Claude 3.7 Sonnet and DeepSeek V3/R1 was chosen for this experiment Apple published a research paper on Saturday, where researchers examine the strengths and weaknesses of recently released reasoning models. Also known as large reasoning models (LRMs), these are the models that "think" by
[20]

Apple Research Finds 'Reasoning' A.I. Models Aren't Actually Reasoning
Apple researchers argue that what we often refer to as "reasoning" may, in fact, be little more than sophisticated pattern-matching. Just as the hype around artificial general intelligence (A.G.I.) reaches a fever pitch, Apple has delivered a sobering reality check to the industry. In a research
[21]

Apple Paper questions path to AGI, sparks division in GenAI group
New Delhi: A recent research paper from Apple focusing on the limitations of large reasoning models in artificial intelligence has left the generative AI community divided, sparking significant debate whether the current path taken by AI companies towards artificial general intelligence is the
[22]

Apple research claims popular AI models fail at hard reasoning: Why does it matter?
Synthetic benchmarks, though valuable, overstate AI limitations by ignoring real-world tools Over the weekend, Apple released new research that accuses most advanced generative AI models from the likes of OpenAI, Google and Anthropic of failing to handle tough logical reasoning problems. Apple's
Share
Copy Link
Apple researchers find that advanced AI reasoning models struggle with complex problem-solving, suggesting fundamental limitations in their ability to generalize reasoning like humans do.
Apple Researchers Challenge AI Reasoning Capabilities
A new study from Apple researchers has cast doubt on the capabilities of advanced AI reasoning models, challenging claims about imminent artificial general intelligence (AGI). The research, titled "The Illusion of Thinking: Understanding the Strengths and Limitations of Reasoning Models via the Lens of Problem Complexity," was conducted by a team led by Parshin Shojaee and Iman Mirzadeh
1
.
Source: Gadgets 360
Study Methodology and Findings
The researchers examined "large reasoning models" (LRMs), including OpenAI's o1 and o3, DeepSeek-R1, and Claude 3.Sonnet Thinking. These models attempt to simulate logical reasoning through a process called "chain-of-thought reasoning"
1
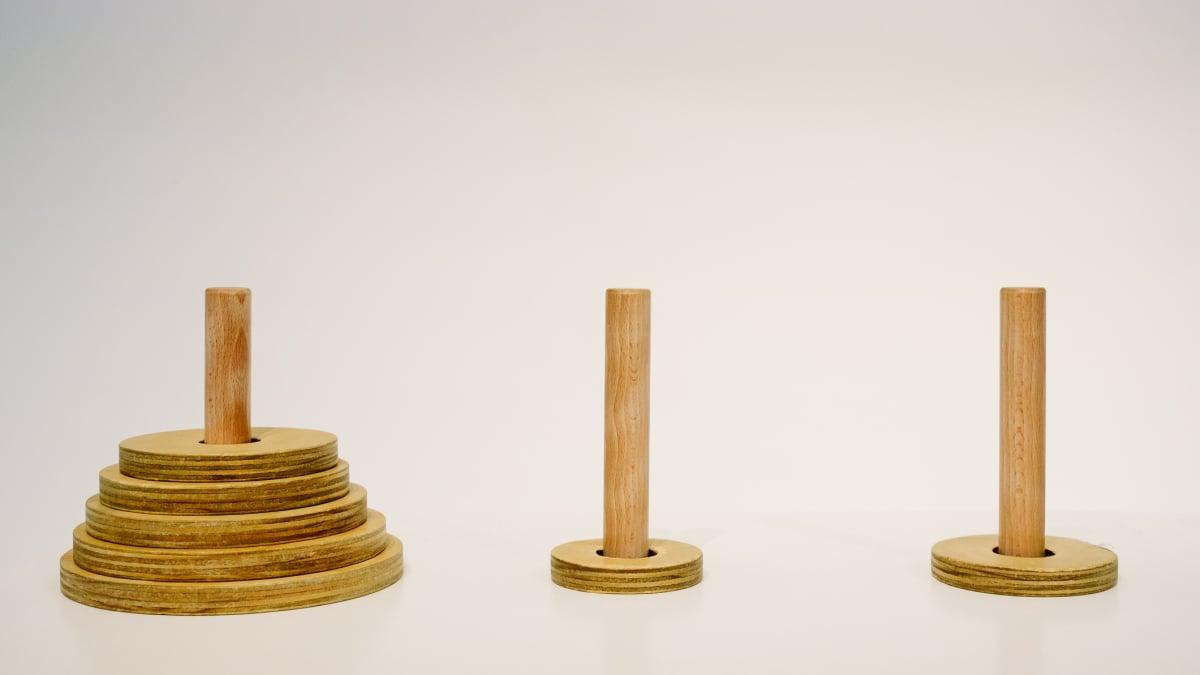
. The study used four classic puzzles - Tower of Hanoi, checkers jumping, river crossing, and blocks world - scaled from easy to extremely complex1
.
Source: Mashable
Key findings include:
- On simple tasks, standard models outperformed reasoning models.
- For moderately difficult tasks, reasoning models had an advantage.
- On highly complex tasks, both types of models failed completely
1
3
.
The researchers also observed a "counterintuitive scaling limit" where reasoning models initially generated more thinking tokens as problem complexity increased, but then reduced their reasoning effort beyond a certain threshold
1
.Implications for AI Development
These results align with a recent study by the United States of America Mathematical Olympiad (USAMO), which found that the same models achieved low scores on novel mathematical proofs
1
. Both studies documented severe performance degradation on problems requiring extended systematic reasoning.AI researcher Gary Marcus, known for his skepticism, called the Apple results "pretty devastating to LLMs"
1
. The study provides empirical support for the argument that neural networks struggle with out-of-distribution generalization.Competing Interpretations
Not all researchers agree with the interpretation that these results demonstrate fundamental reasoning limitations. Some argue that the observed limitations may reflect deliberate training constraints rather than inherent inabilities
1
.University of Toronto economist Kevin A. Bryan suggested that models are specifically trained through reinforcement learning to avoid excessive computation, which could explain the observed behavior
1
. Software engineer Sean Goedecke offered a similar critique, noting that when faced with extremely complex tasks, models like DeepSeek-R1 may decide that generating all moves manually is impossible and attempt to find shortcuts1
.Related Stories
Broader Context and Industry Claims
The study's findings contrast sharply with recent claims by AI industry leaders. Sam Altman of OpenAI and Demis Hassabis of Google DeepMind have made bold predictions about AI capabilities in the 2030s, including solving high-energy physics problems and enabling space colonization
2
.
Source: The Register
However, researchers working with today's most advanced AI systems are finding a different reality. Even the best models are failing to solve basic puzzles that most humans find trivial, while the promise of AI that can "reason" seems to be overblown
2
4
.Limitations and Future Directions
The Apple researchers acknowledge that their study represents only a "narrow slice" of potential reasoning tasks
5
. However, their findings suggest that current approaches to AI development may be encountering fundamental barriers to generalizable reasoning4
.As the AI industry continues to invest heavily in developing more advanced models, with reports of Meta planning a $15 billion investment to achieve "superintelligence"
2
, these research findings highlight the need for a critical examination of AI capabilities and limitations. The gap between industry claims and research findings underscores the importance of continued rigorous testing and evaluation of AI systems as they evolve.References
Summarized by

Navi
[3]
[4]
Related Stories
Apple Study Reveals Limitations in AI's Mathematical Reasoning Abilities
13 Oct 2024•Science and Research

Apple Research Exposes Fundamental Flaws in AI's Logical Reasoning Capabilities
02 Nov 2024•Science and Research

The Turing Test Challenged: GPT-4's Performance Sparks Debate on AI Intelligence
05 Apr 2025•Science and Research

Recent Highlights
1
Apple Launches iOS 27 and macOS 27 with Siri AI Overhaul and Liquid Glass Updates
Technology

2
OpenAI Agents Launched RubyGems Attack With 2,000+ Malicious Packages, Attempted API Key Theft
Technology

3
Apple Launches iPhone 18 Pro with Variable Aperture Camera and Advanced AI Features at $1,199
Technology
Recent Highlights
Today's Top Stories










Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


