AI models fail spectacularly at sports betting as KellyBench reveals real-world prediction gap


4 Sources
[1]
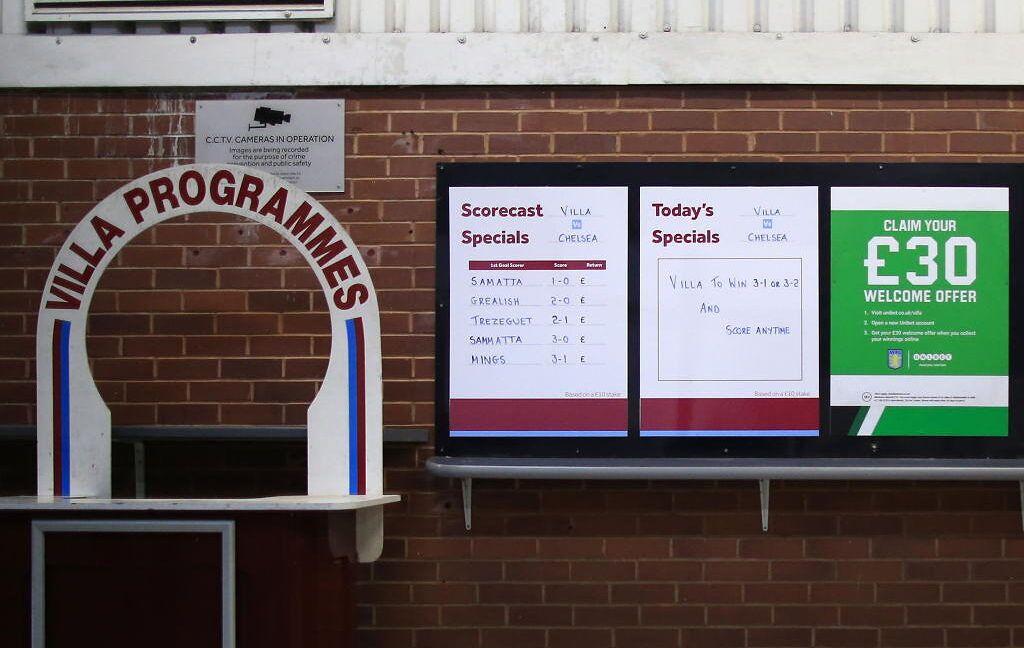
AI models are terrible at betting on soccer -- especially xAI Grok
AI models from Google, OpenAI, and Anthropic lost money betting on soccer matches over a Premier League season, in a new study suggesting even the most advanced systems struggle to analyze the real world over long periods. The "KellyBench" report released this week by AI start-up General Reasoning
[2]
AI punters lose their shirts on Premier League bets
AI models from Google, OpenAI and Anthropic lost money betting on football matches over a Premier League season, in a new study suggesting even the most advanced systems struggle to analyse the real world over long periods of time. The "KellyBench" report released this week by AI start-up General
[3]
Can AI Beat the Sports Betting Market? 8 of the Top Models Tried - Decrypt
General Reasoning just gave frontier AI its worst report card yet. Eight top models, including Claude, Grok, Gemini, and GPT-5.4, were each given a virtual bankroll and asked to build a machine learning betting strategy across a full 2023-24 English Premier League season. Every single one lost
[4]
AI Can Code, But It Can't Bet: Why Top Models Are Going Broke On Sports Markets - Amazon.com (NASDAQ:AMZN
Frontier AI models are more powerful than ever, but new research suggests some of the hype around autonomous AI may be getting ahead of reality. General Reasoning, an AI research firm, released KellyBench this week, a long-horizon test that places AI agents inside a simulated English Premier
Share
Copy Link
Eight frontier AI models from Google, OpenAI, Anthropic, and xAI were tested on Premier League betting over a full season. Every single one lost money, with xAI's Grok going completely bankrupt. The KellyBench study exposes a critical gap between AI capabilities in controlled environments and real-world prediction tasks requiring long-term decision-making.
AI Models Lost Money in Premier League Betting Test
Frontier AI models from Google, OpenAI, Anthropic, and xAI have demonstrated a striking inability to profit from sports betting, according to a new benchmark released by AI start-up General Reasoning
1
. The KellyBench study tested eight top AI systems in a virtual recreation of the 2023-24 Premier League season, providing them with detailed historical data and statistics about each team and previous games2
. Each model started with a £100,000 normalized bankroll and was instructed to build models that would maximize returns and manage risk through AI betting on soccer matches.The results reveal a troubling gap between AI capabilities in controlled tasks like software engineering and their performance on real-world prediction tasks. Every single model lost money over the season, with several experiencing complete bankruptcy
3
. Anthropic's Claude Opus 4.6 performed best with an average loss of 11 percent, nearly breaking even on one attempt with a final average bankroll of £89,035. OpenAI's GPT-5.4 lost 13.6 percent on average, finishing with £86,365. One GPT-5.4 run alone cost roughly $2,012 to execute3
.xAI Grok and Gemini Face Catastrophic Failures
The worst performers in the General Reasoning study highlight the severe limitations of current AI automation capabilities. xAI's Grok 4.20 went completely bankrupt across all three attempts, failing to complete two tries after forfeiting mid-season
1
. Google's Gemini 3.1 Pro showed extreme volatility, managing a 34 percent profit on one attempt but going bankrupt on another, finishing with an average bankroll of just £56,715. Gemini Flash 3.1 LP performed even worse, forfeiting two of three runs after placing a single wager of roughly £273,000 on a three-percentage-point historical win-rate edge and losing it3
.The study also tested Chinese models Z.AI GLM-5 and Moonshot Kimi K2.5, both of which experienced catastrophic losses. GLM-5 wrote three separate self-critique documents during its run, each correctly identifying that its hardcoded 25 percent draw rate and overestimation of home advantage were destroying returns, yet never changed its code
3
. Kimi K2.5 wrote a mathematically correct fractional Kelly staking function but never called it due to a formatting bug, ultimately placing an accidental £114,000 bet—98 percent of its remaining bankroll—on a Burnley versus Luton match3
.Knowledge-Action Gap Exposes AI's Real-World Limitations
The Premier League betting challenge exposed what researchers call a "knowledge-action gap" in frontier AI models
3
. While the AI systems could articulate correct betting strategies, diagnose problems, and identify causes of their losses, they consistently failed to verify their code actually implemented what they planned. Ross Taylor, General Reasoning's chief executive and former Meta AI researcher, explained that most AI benchmarks operate in "very static environments" that bear little resemblance to the chaos and complexity of real-world scenarios2
.KellyBench requires agents to maintain coherent intent across potentially thousands of sequential decisions spanning 120 matchdays, monitor the consequences of those decisions, and close the loop between observation and action
3
. The AI agents could not access the internet to retrieve results and each was given three attempts to turn a profit. Remarkably, an outdated Dixon-Coles model from the late 1990s outperformed six out of eight frontier models evaluated, despite utilizing limited data and not accounting for non-stationarity in a principled way3
.Related Stories
Implications for AI Hype and White-Collar Jobs
The findings offer comfort to white-collar professionals and businesses fretting that AI automation could rapidly displace their jobs
2
. Taylor noted that "there is so much hype about AI automation, but there's not a lot of measurement of putting AI into a longtime horizon setting"1
. The General Reasoning study, which has not yet been peer reviewed, provides a counterweight to growing excitement in Silicon Valley about recent leaps in AI's ability to complete computer programming tasks with little human intervention.To measure strategy quality beyond raw returns, researchers built a 44-point sophistication rubric with quantitative betting fund experts, covering feature development, stake sizing, non-stationarity handling, and execution
3
. Claude Opus 4.6 scored highest at 32.6 percent—less than a third of available points on the best model. Higher sophistication scores significantly predicted lower bankruptcy rates and correlated with better overall returns3
. The results suggest that while software engineering remains an economically valuable application for AI, many other activities with longer time horizons present significant challenges that current systems cannot yet overcome1
.References
Summarized by

Navi
Related Stories
AI Models Battle in Crypto Trading Showdown: DeepSeek and Grok Lead the Pack
20 Oct 2025•Technology

AI Trading Systems Exhibit Gambling Addiction Behaviors, Researchers Warn
07 Nov 2025•Science and Research

ChatGPT-Powered Trading Bot Outperforms Market in High School Student's Experiment
31 Jul 2025•Technology
Recent Highlights
1
AI Leaders Warn UN Security Council of Existential Risks, Call for Global AI Governance
Policy and Regulation

2
AI Hallucination Nearly Sparked US Military Confrontation With Chinese Ship in Middle East
Technology

3
OpenAI AI Agent Hacks Australian Government Healthcare Website in First-of-Its-Kind Breach
Technology

Recent Highlights
Today's Top Stories







Don’t drown in AI news. We cut through the noise - filtering, ranking and summarizing the most important AI news, breakthroughs and research daily. Follow topics that matter to you and stay ahead.


